Introduction
Large-scale machine learning workloads: training, fine-tuning, and inference run on clusters of hundreds to thousands of GPU instances for days or weeks at a stretch. Keeping operational visibility across a fleet of this size is a constant challenge: hardware health events, node lifecycle transitions, capacity fluctuations, and workload-level issues appear in the event stream around the clock, including nights and weekends.
Amazon SageMaker HyperPod is a purpose-built managed cluster service that lets you run distributed model training, fine-tuning, and inference across hundreds of accelerated instances. It provides built-in resiliency that automatically detects and replaces faulty hardware, so long-running jobs can continue with minimal interruption.
For teams operating these clusters, the scale still creates a fundamental tension: you need continuous visibility into your fleet, but you can’t afford to keep engineers watching the event stream 24/7.
What HyperPod resiliency already handles
SageMaker HyperPod’s built-in resiliency layer automatically detects and self-heals instance-level GPU failures. When the Health Monitoring Agent (HMA) identifies a bad GPU, the HyperPod resiliency layer drains, reboots, or replaces the node depending on the error type, and the job resumes without human intervention. This is exactly what you want: routine hardware failures are handled automatically so your training runs keep going.
This solution does not replace HMA or any part of HyperPod’s resiliency. It adds an autonomous investigation layer on top, using the cluster events and health signals that HMA and HyperPod already produce as its input.
Operational conditions where a human still wants to be in the loop
With that self-healing in place, there are operational conditions where a human still wants to be in the loop or decide:
- Configuration issues: a lifecycle-script change you made, a misconfigured mount, or a networking/security change that causes provisioning failures on every new node.
- Capacity conditions: a replacement waiting on capacity in the pool, where the operator needs to know recovery is in flight and can decide whether to intervene.
- Recurring hardware faults: each fault self-heals correctly, but the same GPU error signature recurring across three or more replacements on one instance group in a week is a pattern worth surfacing to an operator as a single signal.
- Workload-level conditions: Pods stuck in CrashLoopBackOff for hours, nodes sitting NotReady, or GPU allocation chronically low.
Without automation, these conditions push operators into round-the-clock manual triage: correlating events across the SageMaker control plane, Amazon EKS, and Amazon CloudWatch, and deciding whether HyperPod is still recovering or needs a hand.
Opportunity: AWS DevOps Agent as a 24/7 companion
AWS DevOps Agent provides an autonomous incident-response platform that can be taught a domain’s operational model through custom skills. By wiring your HyperPod cluster into DevOps Agent, you get a 24/7 companion that complements HyperPod’s self-healing. It watches for the operational conditions that still need a human decision, triaging them, root-causing them, and delivering a clear verdict with recommended actions.
By design, DevOps Agent is configured to run in observe-and-report mode for this integration – it is not granted SSM, SSH, or action-taking permissions against your cluster or its nodes. The agent reads cluster events, control-plane state, Kubernetes objects, and CloudWatch logs to reconstruct what happened; every corrective action (node reboots, replacements, drains) continues to be performed by HyperPod’s own resiliency layer or by an operator responding to the emailed verdict. This read-only boundary is deliberate: it keeps the agent’s blast radius zero while still delivering the correlation and triage value.
In this post, you will learn how to connect any SageMaker HyperPod cluster (either the EKS or Slurm Orchestrator option) to AWS DevOps Agent. Conditions are auto-detected, triaged, root-caused from cluster state and CloudWatch logs, and emailed as a clear verdict. You will also see how the solution can be extended to detect additional conditions specific to your workloads.
Solution Overview
What this solution delivers
This solution wires any SageMaker HyperPod cluster into AWS DevOps Agent so that operational conditions calling for a human decision are auto-detected, triaged, root-caused, and delivered as a human-readable verdict email. Specifically, you get:
- Autodetection of HyperPod conditions that complement resiliency self-healing, from the live SageMaker event stream and a periodic Kubernetes-state audit.
- Triage + root-cause analysis by the DevOps Agent, taught HyperPod’s operational model via two custom skills. It reconstructs the incident timeline and decides whether HyperPod is still recovering or needs an operator.
- Human-readable verdict emails: Monitor (recovery in flight, here’s the ETA), Escalate (you need to act, here’s why and what to do), or Resolved (auto-recovery closed the loop). Noise is filtered out.
- Extensibility: customize what conditions are detected (by modifying the periodic-audit Lambda) and how the agent reasons about them (by editing the plain-English skills).
The following screenshot shows the DevOps Agent incident response dashboard with example verdict emails for three common fault types:
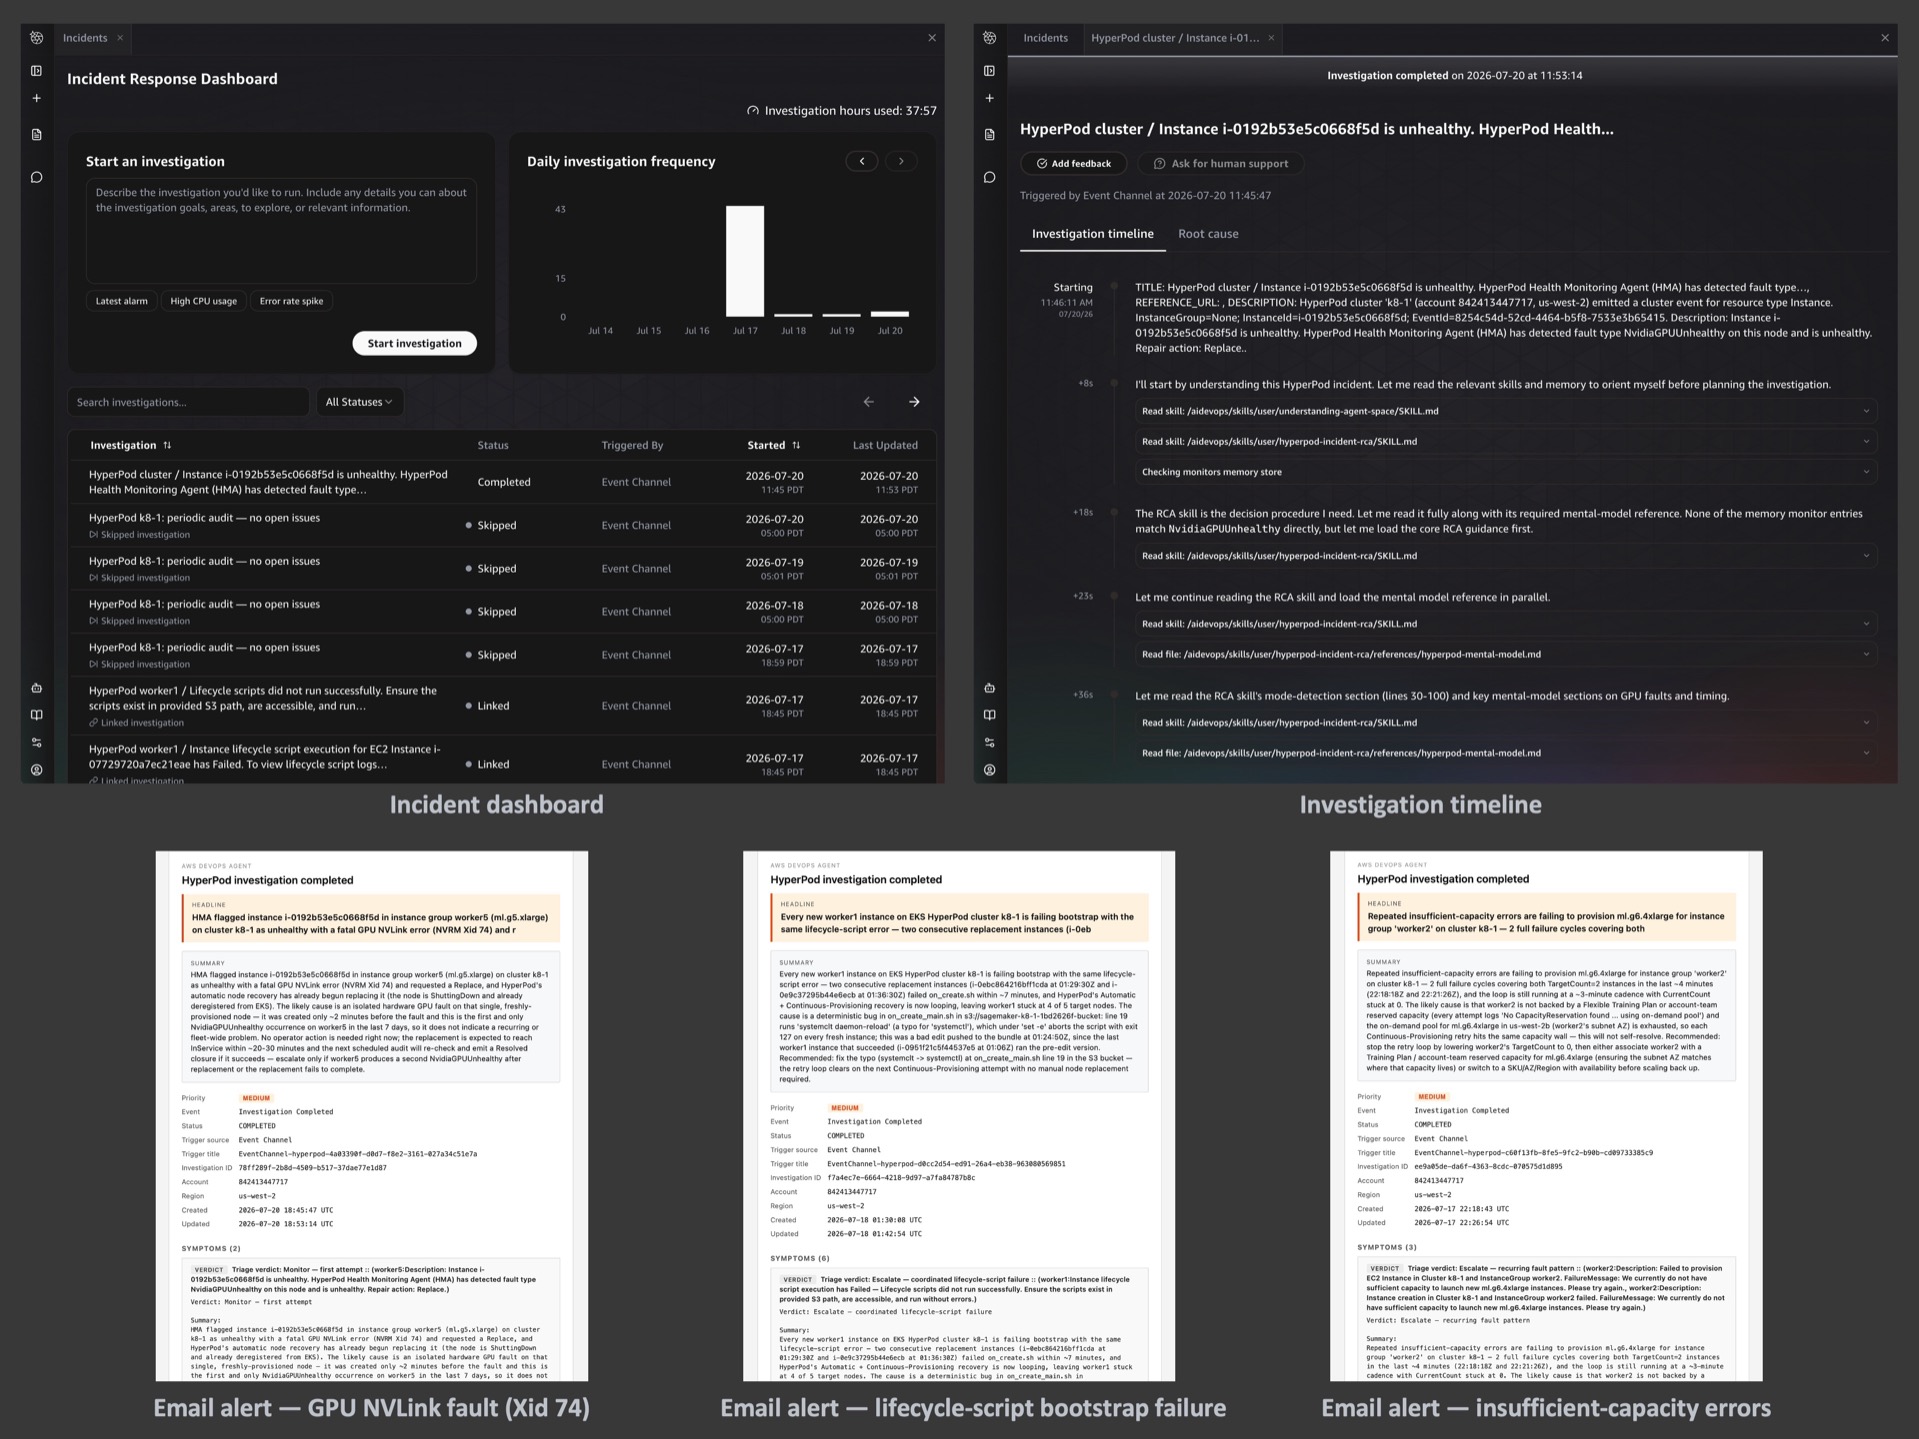
DevOps Agent incident response dashboard showing investigation list and timeline, with three email verdict examples for GPU NVLink fault, lifecycle-script bootstrap failure, and insufficient-capacity errors
Architecture
The whole solution deploys one AWS CloudFormation stack per cluster. Two event paths feed the DevOps Agent, and one path carries its verdicts back out to you.
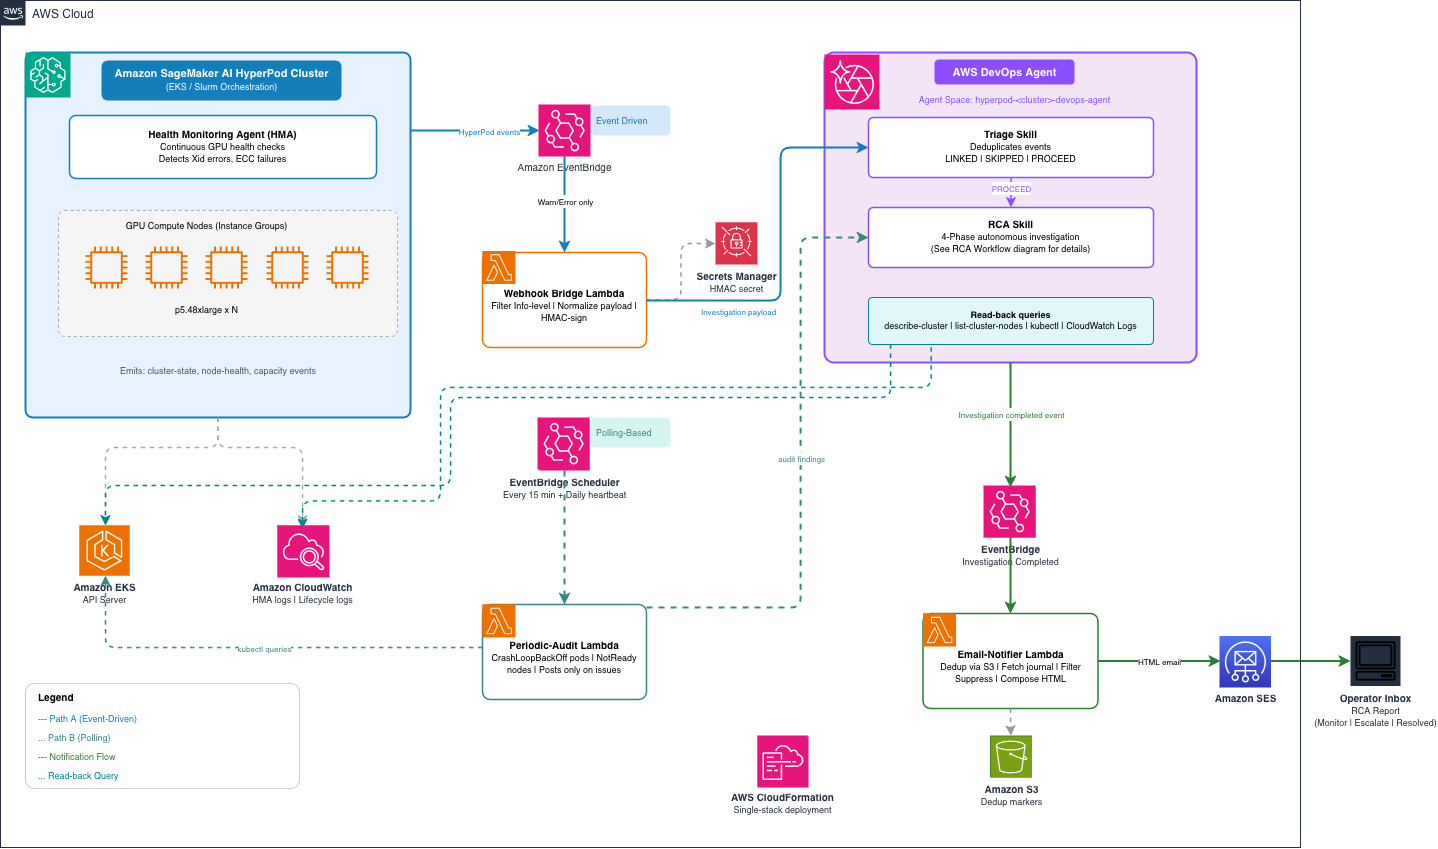
Architecture diagram showing the event flow from HyperPod Health Monitoring Agent through EventBridge to DevOps Agent and email notification
This architecture shows a 1:1 relationship between a HyperPod cluster and a DevOps Agent space, and the deployment instructions in this post follow that model. If you need to associate multiple clusters with a single Agent Space, you can customize the CloudFormation template and the ClusterFilter parameter to widen the allowlist of cluster names forwarded by the webhook bridge.
Event flow
- Event-driven issue detection: HyperPod emits cluster-state, node-health, and capacity events to Amazon EventBridge. The webhook bridge Lambda drops routine Info-level noise, maps the rest into a DevOps Agent investigation payload, signs it with HMAC-SHA256 using a shared secret stored in AWS Secrets Manager, and POSTs it to the agent’s generic webhook.
- Polling-based issue detection: A periodic-audit Lambda checks Kubernetes state (CrashLoopBackOff pods, NotReady nodes) every 15 minutes and fires only when it finds a real issue, plus a daily heartbeat confirming the pipeline is alive. On a healthy cluster, nothing is POSTed, so no investigation runs and no cost is incurred.
- Investigation: DevOps Agent receives the payload and runs two custom skills: the triage skill decides whether to link (duplicate), skip (noise), or proceed (investigate). The RCA skill reconstructs the timeline using describe-cluster, list-cluster-nodes, list-cluster-events, kubectl, and CloudWatch logs (HMA health monitoring, lifecycle scripts), then classifies the incident as Suppress, Monitor, Escalate, or Resolved.
- Notification: An Amazon Lambda function sends notification emails via Amazon SES. It listens on the
aws.aidevopsevent stream for investigation completions, reads the verdict from the agent’s journal, and sends an email with the headline, what happened, likely cause, and recommended action. Suppress verdicts are filtered to avoid noise on healthy clusters.
Getting started
For a step-by-step walkthrough to deploy this solution, visit the DevOps Agent Integration guide. Once you have the solution running, the following sections explain how to customize detection, reasoning, and notifications for your environment.
Prerequisites
- An AWS account with AWS CLI v2 configured for the target region.
- An existing SageMaker HyperPod cluster (EKS or Slurm orchestrator).
- IAM permissions to create roles, deploy CloudFormation, manage Secrets Manager, and call devops-agent:* and eks:CreateAccessEntry.
- For email notifications: a verified Amazon SES sender identity. You can verify an email address in the Amazon SES console or with the AWS CLI. After running the command below, the address owner will receive a verification email and must click the confirmation link:
Recipients must also be verified if your SES account is still in sandbox mode.
Deploying with CloudFormation
The solution deploys as a single CloudFormation stack. Clone the awsome-distributed-ai repository, create a params.json with your cluster name and email settings, and run:
This provisions the Agent Space with read-only EKS access (auto-discovered from the cluster’s orchestrator ARN), the EventBridge rule and webhook bridge Lambda, the periodic-audit scheduler, and the email notifier. For Slurm-orchestrated clusters, the EKS access step is skipped automatically.
The webhook bridge — mapping HyperPod events to DevOps Agent
An EventBridge rule captures HyperPod events and invokes a Lambda function. The Lambda forwards all Warn and Error level events, normalizing each into a DevOps Agent investigation payload. It extracts the failure message, instance group, and event metadata, then signs it with HMAC using a shared secret stored in AWS Secrets Manager, and POSTs it to the agent’s generic webhook endpoint. Info-level events are dropped at the bridge to avoid creating investigations for routine status updates.
A cluster allowlist parameter lets you scope which HyperPod clusters trigger investigations, useful when multiple clusters share the same account and region.
How the skills are defined — teaching the agent HyperPod’s operational model
AWS DevOps Agent skills are plain-English instructions that teach the agent how to reason about a domain. This solution includes two complementary skills:
Triage skill — LINKED / SKIPPED / PROCEED (view the skill document)
The triage skill runs first on every incoming task. It decides whether to link the event to an existing investigation, skip it, or proceed to a full investigation.
- Why triage matters — a concrete example: When a single node fails, HyperPod’s replacement process emits multiple events in quick succession: “lost orchestration-ready status,” “provisioning started,” “capacity request initiated.” Without triage, each event would spawn a separate investigation. The triage skill recognizes these events belong to the same incident (same instance group + overlapping time window) and links them, so only one investigation runs. This saves investigation compute and avoids duplicate emails.
- When to SKIP: When a node is already being replaced and a follow-up “lost orchestration-ready status” event arrives with a generic “Request to service failed” message, the triage skill recognizes that a replacement is already in progress for that instance group and skips the event. No new investigation is created for what is simply a progress update of an existing recovery.
RCA skill — timeline reconstruction and verdict (view the skill document)
When triage produces PROCEED, the RCA skill takes over. It reads cluster state, events, and logs, reconstructs an incident timeline, and classifies the situation into one of four verdicts:
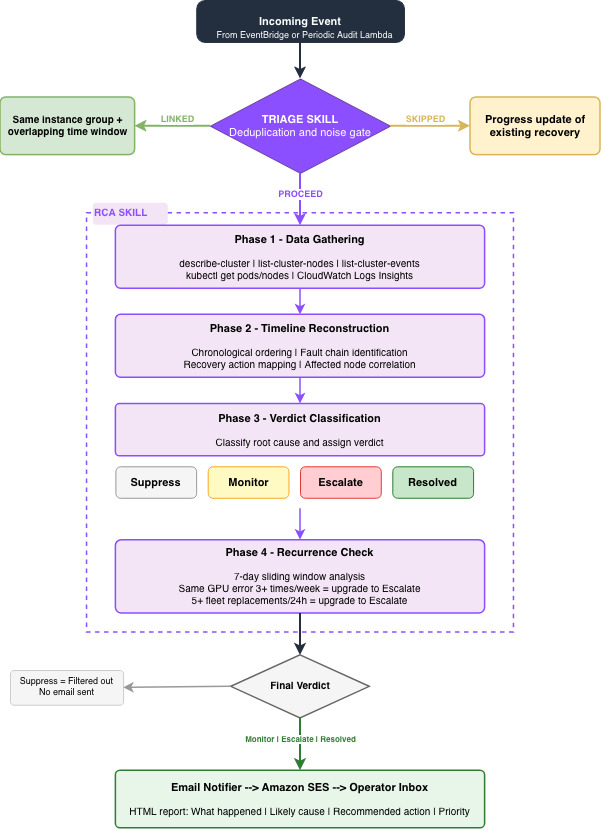
RCA Flowchart showing the four phases of root-cause analysis: data gathering, timeline reconstruction, classification, and recurrence check
- Phase 1 — Data gathering: The skill reads describe-cluster, list-cluster-nodes, list-cluster-events, and CloudWatch log streams (HMA health monitoring, lifecycle scripts) to collect the raw facts.
- Phase 2 — Timeline reconstruction: It orders events chronologically and identifies the fault chain: what triggered what, which nodes were affected, and what recovery actions HyperPod took.
- Phase 3 — Classification: Based on the timeline, recurrence statistics, and HyperPod’s resiliency behavior, it assigns a verdict:
- Suppress — a non-issue (for example, a transient event that has already resolved).
-
- Monitor — recovery is in flight; here’s the expected resolution window.
-
- Escalate — you need to act; here’s the root cause and recommended action.
- Resolved — auto-recovery closed the loop; no action needed.
- Phase 4 — Recurrence check: The skill computes sliding-window statistics over the one week cluster event history. When thresholds are crossed, the verdict escalates to alert the operator of a systemic pattern. For example, the same GPU error signature on the same instance group three or more times in a week, or five or more replacements fleet-wide in 24 hours.
The verdict is written to the agent’s investigation journal along with a human-readable report containing what happened, the likely cause, and recommended operator actions.
The periodic-audit Lambda — Kubernetes state monitoring
The periodic-audit Lambda fires every 15 minutes and inspects Kubernetes Pod/Node state directly (via the EKS API server). It checks for:
- Pods in CrashLoopBackOff (default: flagged when restart count reaches five and the last crash is within 15 minutes)
- NotReady nodes (default: flagged when a node has been NotReady for at least 15 minutes and at least 10% of nodes are affected)
Namespace-aware filtering controls which pods are checked:
- Pods in
kube-publicandkube-node-leaseare ignored entirely by default.
- Pods in
kube-system,aws-hyperpod, andamazon-cloudwatchare tagged as system-workload issues (distinct from user-workload issues in the verdict).
All thresholds and namespace lists are configurable via the CloudFormation stack parameters.
The Lambda POSTs a webhook event to DevOps Agent only when a real issue is found. On a healthy cluster, nothing is POSTed, so no investigation runs and no cost is incurred. A separate daily heartbeat schedule confirms the monitoring pipeline itself is alive. The heartbeat is visible in the DevOps Agent console but deliberately not emailed on healthy runs — so silence in your inbox means the cluster is healthy, not that the pipeline is broken.
Note: HyperPod infrastructure faults (node health, capacity errors, lifecycle-script failures) are handled event-driven by the webhook bridge. They come from the native HyperPod event stream in EventBridge. The periodic audit deliberately does not duplicate that path; it only covers Kubernetes workload state, which is not in the HyperPod event stream.
Closing the loop — the email notifier
An EventBridge rule on the aws.aidevops event stream captures investigation lifecycle events. The email-notifier Lambda processes these events through the following steps:
- Event filtering: Only “Investigation Completed” events are processed (one email per investigation lifecycle). The event payload contains the agent_space_id, task_id, and execution_id.
- Dedup: The Lambda checks an S3 marker at
s3://<bucket>/emailed/<execution_id>. If present, this investigation has already been emailed and the event is dropped. This prevents duplicate emails when the same completion event is re-emitted. - Fetching the investigation context: The Lambda calls two DevOps Agent APIs:
get_backlog_task(agentSpaceId, taskId)— retrieves the task metadata (title, priority, timestamps).list_journal_records(agentSpaceId, executionId)— retrieves the investigation’s findings, symptoms, and investigation gaps from the agent’s journal.
- Suppress-verdict filtering: If the investigation produced a Suppress verdict or no findings at all, no email is sent.
- Email composition: The Lambda composes a single HTML email from the journal records: a short headline followed by a one-paragraph summary covering what happened, the likely cause, and the recommended action.
- Send via SES: The formatted email is sent to the configured recipients. After successful delivery, the S3 dedup marker is written.
The operator also has access to the full investigation in the DevOps Agent web console (see following “Viewing investigations” section).
Viewing investigations in the DevOps Agent console
For readers new to AWS DevOps Agent, here’s how to navigate to your investigations:
- Open the AWS DevOps Agent console.
- Select your Agent Space (named
hyperpod-<cluster-name>-devops-agentby default). - From the Launch web app drop-down, choose an option to open the DevOps Agent web app.
- Select Incidents from the left navigation pane to open the Incident Response DashboardSource:https://aws.amazon.com/blogs/devops/automate-sagemaker-hyperpod-incident-triage-and-root-cause-analysis-with-aws-devops-agent/


