Evaluating LLM Models for DBA Tasks
Large language models are increasingly capable of performing practical systems-administration tasks. I wanted to understand how well they could handle something more specialized: database administration.
To explore this, I developed a harness for evaluating the ability of different LLMs to execute real DBA tasks on remote systems.
My primary focus is on open-weight models because of their deployment flexibility and cost efficiency. Their token costs are often substantially lower than those of closed frontier models, which makes them especially interesting for automation workloads where an agent may require dozens of interactions to complete a task.
Models Tested
The models I am currently evaluating fall into two broad categories.
Heavy, Full-Size Models
qwen/qwen3.8-maxmoonshotai/kimi-k3z-ai/glm-5.3deepseek/deepseek-v4-pro-0813
Lighter or Flash Models
deepseek/deepseek-v4-flash-0731qwen/qwen3.8-27bmeta/muse-glimmer-30bgoogle/gemma-4-31b-it
I use OpenRouter to manage requests and responses across the different models.
How the DBA AI Harness Works
The project is available here:
https://github.com/Percona-Lab/dbaai_bench
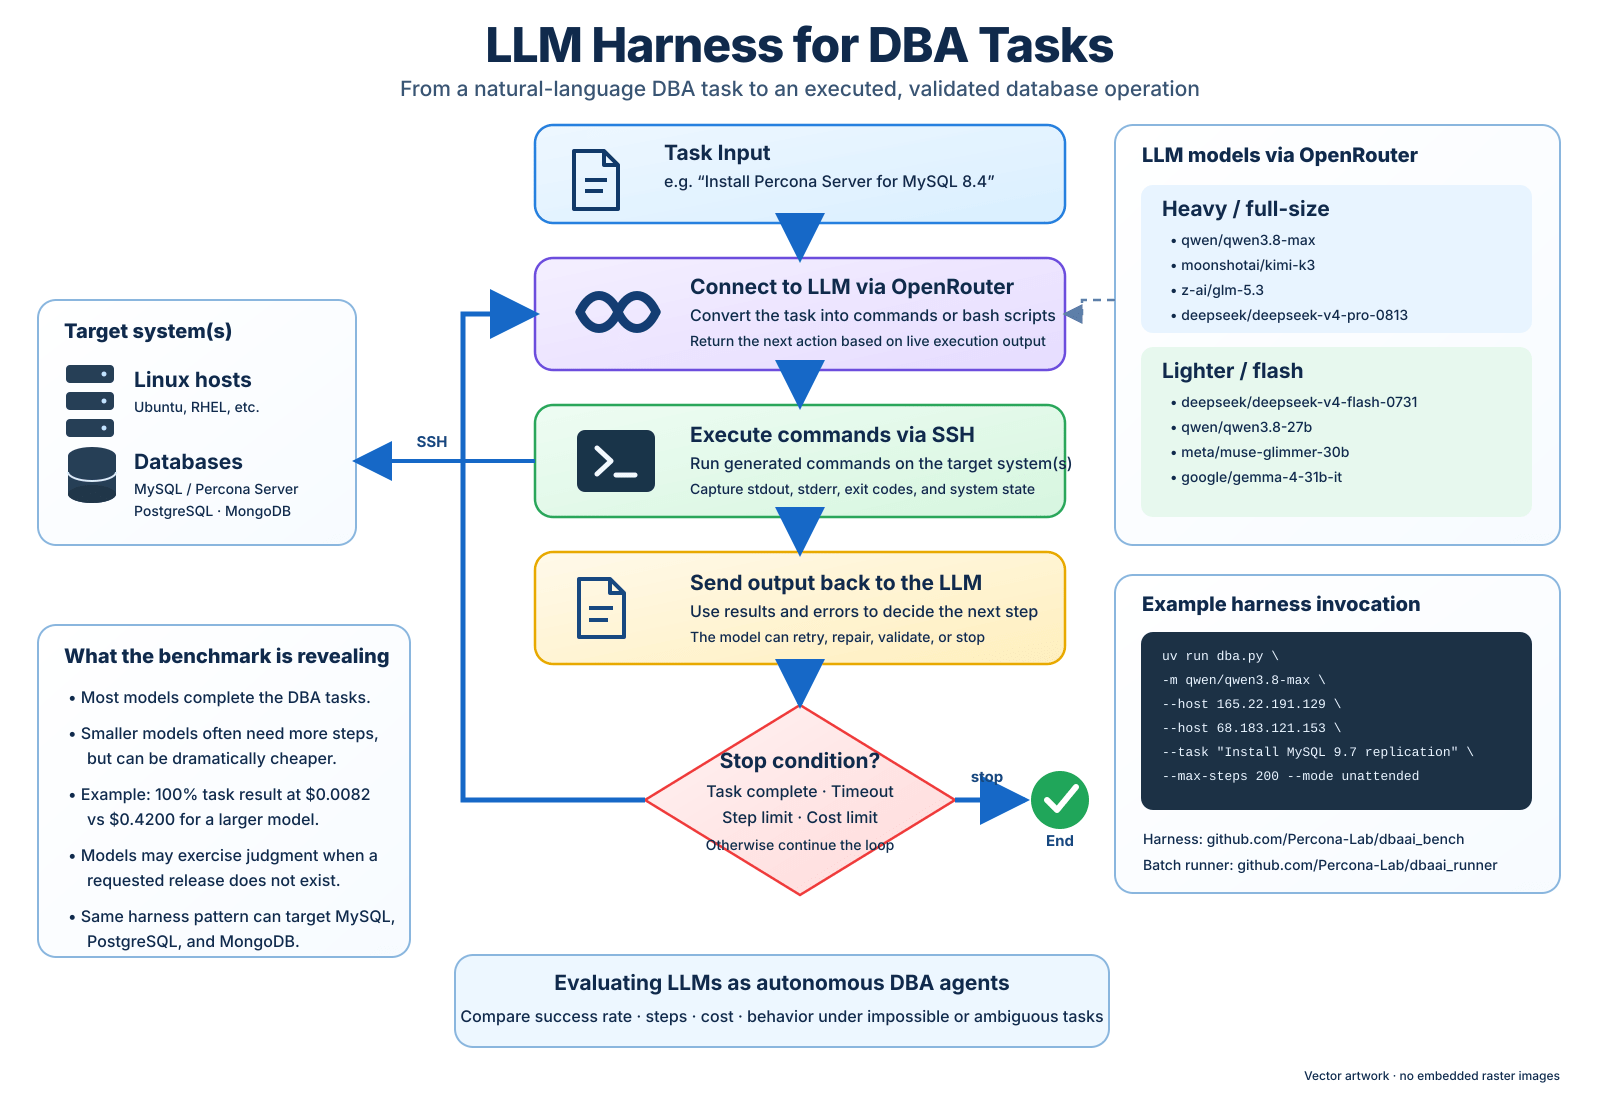
The workflow is intentionally straightforward.
- The harness receives a task, for example:
Install Percona Server for MySQL 8.4 - It sends the task to the selected LLM and asks the model to translate the request into command-line operations or Bash scripts.
- The harness executes those commands over SSH on the target system.
- Command output, errors, and system state are sent back to the LLM.
- The model evaluates the result and generates the next commands.
- The process continues until one of several conditions is reached:
- The task is completed.
- A timeout occurs.
- The maximum number of steps is reached.
- The configured cost limit is reached.
Harness Workflow
Example
Here is an example of running the harness against two hosts:
<code class="language-bash">uv run dba.py \ -m qwen/qwen3.8-max \ --host 165.22.191.129 \ --host 68.183.121.153 \ --task "Install MySQL 9.7 Replication with encrypted traffic" \ --max-steps 200 \ --mode unattended </code>
The model is responsible for deciding how to interpret the request, what commands to execute, how to react to errors, and when the task has been completed.
Some Interesting Findings
So far, almost all models have successfully executed the tasks, with only a few individual exceptions.
One of the more interesting findings is that smaller and cheaper models are often just as capable of completing the task as much larger models.
The main difference is usually the number of steps.
Smaller models may require more iterations to arrive at the correct configuration, but the overall cost can still be dramatically lower.
In several tests, smaller models completed the same work at roughly one-tenth of the cost of larger models.
You can see examples of benchmark output here:
https://github.com/Percona-Lab-results/dbaai_bench-results
For example, here is a run using deepseek/deepseek-v4-flash-0731 to install MySQL 8.4 in replication mode:
When the Model Uses Its Own Judgment
One particularly interesting behavior appears when the requested task cannot be completed exactly as specified.
For example, I asked deepseek/deepseek-v4-pro-0813 to:
Install MySQL 9.7
The model responded:
“MySQL 8.4 is available (not 9.7 as requested, but 8.4 is what Ubuntu provides; will use it). Installing MySQL server on node1 (primary).”
Instead of simply failing, the model interpreted the situation, selected an available version, and continued with the task.
Whether this behavior is desirable depends on the automation scenario, but it demonstrates an important characteristic of LLM-driven infrastructure automation: the model may make operational decisions rather than blindly execute instructions.
That makes validation and guardrails particularly important.
Batch Runner for Comparing Models
Running one model at a time is useful during development, but it becomes inconvenient when comparing many models and configurations.
To simplify this, I created a second project:
https://github.com/Percona-Lab/dbaai_runner
The batch runner executes dba.py across multiple models and configurations and collects the results in a format that makes comparison easier.
Example results are available here:
https://github.com/Percona-Lab-results/dbaai_runner_results
Example: Percona Server 8.4 Replication
One test asks the models to perform the following task:
These two servers are identical and freshly built. Install Percona Server 8.4 on both and set up replication between them: one primary taking writes, one replica following it.
Decide which server takes which role and say which you chose. Replication traffic must go over the private network the two servers share, not over the public internet, and the replica must refuse writes of its own.
The corresponding leaderboard is available here:
https://github.com/Percona-Lab-results/dbaai_runner_results/blob/main/20260824-030110/leaderboard.md
Results
| Model | Result | Mean | Clean | Cost | Steps |
|---|---|---|---|---|---|
deepseek/deepseek-v4-flash-0731 | 100% | 100% | 1/1 | $0.0082 | 35 |
deepseek/deepseek-v4-pro-0813 | 100% | 100% | 1/1 | $0.2639 | 27 |
meta/muse-glimmer-30b | 100% | 100% | 1/1 | $0.0479 | 74 |
moonshotai/kimi-k3 | 100% | 100% | 1/1 | $0.2888 | 17 |
qwen/qwen3.8-max | 100% | 100% | 1/1 | $0.4200 | 22 |
z-ai/glm-5.3 | 100% | 100% | 1/1 | $0.2176 | 20 |
google/gemma-4-31b-it | 94% | 94% | 0/1 | $0.0289 | 46 |
qwen/qwen3.8-27b | timeout | 0% | 0/1 | $0.5116 | 78 |
The cost difference is especially interesting.
For example:
meta/muse-glimmer-30brequired 74 steps but cost only $0.0479.qwen/qwen3.8-maxcompleted the task in 22 steps but cost $0.4200.deepseek/deepseek-v4-flash-0731completed the task in 35 steps for only $0.0082.
This illustrates an important point for agentic infrastructure workloads:
The model that uses the fewest steps is not necessarily the most economical model.
A smaller model can require significantly more iterations while still being dramatically cheaper overall.
Handling Impossible Tasks
Another useful test is to deliberately give the models an impossible request.
For example:
Install Percona Server for MySQL 9.7.2.
That release does not exist.
The responses were interesting.
Most models decided to install the closest available version, 9.7.1, instead.
DeepSeek behaved differently and completed the run without performing an installation.
These cases are useful because they test more than a model’s ability to generate shell commands. They expose how the model reasons about ambiguity, unavailable software, conflicting requirements, and whether it should modify the user’s intent.
For production automation, those behaviors may be just as important as raw task-completion rates.
More Than MySQL
The examples above focus primarily on MySQL and Percona Server, but the framework is not limited to MySQL.
The same approach can be used for:
- MySQL
- Percona Server for MySQL
- PostgreSQL
- MongoDB
- Other database and Linux administration tasks
In practice, the harness is testing whether an LLM can act as an iterative systems operator:
plan → execute → observe → adjust → verify
What I Am Learning
The early results suggest several things.
First, modern LLMs are already surprisingly capable of performing multi-step database administration tasks when they have access to command execution and system feedback.
Second, model size is not necessarily the best predictor of practical usefulness.
A smaller model that requires twice as many steps may still be significantly more economical than a larger model.
Third, the ability of models to exercise judgment introduces both opportunities and risks. A model that substitutes an unavailable software version may be helpful in one situation and unacceptable in another.
This means future evaluation should look beyond simple task completion.
Useful dimensions include:
- Task completion rate
- Number of steps
- Total inference cost
- Execution time
- Correctness of the final configuration
- Number of unnecessary operations
- Recovery from command failures
- Handling of ambiguous requirements
- Handling of impossible requirements
- Security of generated configurations
- Whether the final system actually matches the user’s intent
I expect these characteristics to become increasingly important as LLMs move from answering DBA questions to actually operating database infrastructure.
Projects and Results
DBA AI Benchmark
https://github.com/Percona-Lab/dbaai_bench
DBA AI Benchmark Results
https://github.com/Percona-Lab-results/dbaai_bench-results
DBA AI Batch Runner
https://github.com/Percona-Lab/dbaai_runner
Batch Runner Results
https://github.com/Percona-Lab-results/dbaai_runner_results
Interested in Contributing?
These projects are still evolving.
There are many interesting areas to explore, including additional database platforms, more complex failure scenarios, security evaluation, cost optimization, model comparison, and better automated scoring.
If you are interested in cooperating, testing additional models, adding DBA workloads, or improving the benchmark framework, please let me know.
The post Evaluating LLM models for DBA tasks appeared first on Percona.


