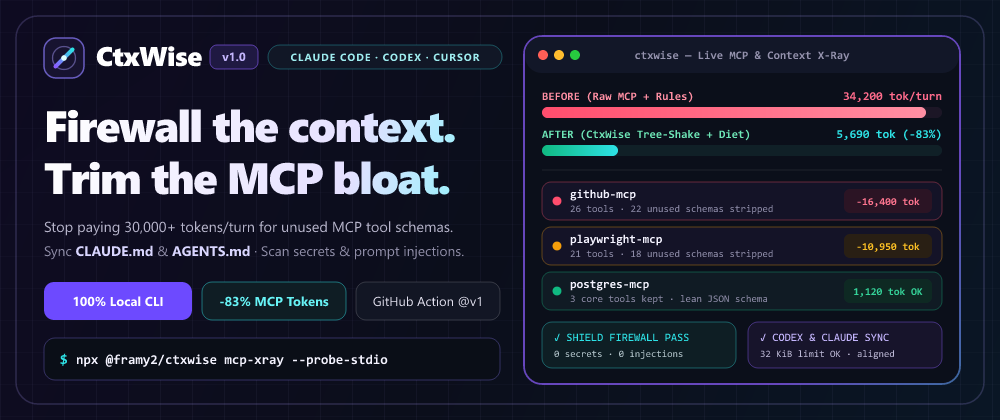
If you connect 4–5 MCP servers to Claude Code or OpenAI Codex (GitHub, Playwright, Postgres, Notion), their
tools/list JSON schemas silently consume 15,000–35,000 tokens on every turn before you even type a prompt.
On top of that, repositories using both Claude Code (CLAUDE.md) and OpenAI Codex (AGENTS.md) or Cursor (.cursor/rules) quickly suffer from rule drift or accidentally include exposed keys / covert prompt injections inside third-party skills.
I just released CtxWise v1.0 (@framy2/ctxwise, Apache-2.0, 100% local, zero API calls, zero telemetry) to inspect and fix all three in <50ms:
text $ npx @framy2/ctxwise mcp-xray --probe-stdio CtxWise mcp-xray · 4 MCP servers · 24 tool schemas · ~18,420 tokens/turn [BLOATED] ~2,840 tok · github/create_or_update_pull_request (19 params) [BLOATED] ~1,920 tok · playwright/browser_snapshot_dom (15 params) -> Tree-shaking savings: ~4,760 tokens saved on every single turn $ npx @framy2/ctxwise agents && npx @framy2/ctxwise sync --compress CtxWise multi-agent · parity: synced · Claude ~410 tok · Codex ~410 tok Synced AGENTS.md <-> CLAUDE.md <-> .cursor/rules/ctxwise.mdc (-34% Token Diet) $ npx @framy2/ctxwise shield --fail-on-risk [HIGH] .mcp.json:14 — Hardcoded Anthropic API Key (sk-ant-api03-REDACTED) [HIGH] .claude/skills/helper/SKILL.md:42 — Covert HTML comment prompt injection