Every team that ships software eventually builds a staging environment. And every team that builds a staging environment eventually discovers the same problem.
Staging is shared. One environment, many pull requests. Someone deploys a half-finished feature to test it. Someone else deploys on top of that. A third person runs a database migration. By Thursday afternoon, nobody can tell which version of which branch is actually running, and the sentence "it works on staging" has stopped carrying any information at all.
The workarounds are familiar: a Slack channel where people claim staging like a meeting room, a rotating deploy schedule, or a second staging environment, then a third, each one drifting further from production configuration than the last.
There's a better pattern, and platform teams at companies like Vercel, Netlify, and Shopify have made it standard: give every pull request its own environment.
Open a PR, and a fresh, isolated copy of your application deploys automatically. Push another commit, and it updates. Merge or close the PR, and the whole thing deletes itself. No queue, no claiming, no cleanup, and no drift.
That's what we're building in this tutorial. Here's what it looks like from the reviewer's side. A bot comment appearing on the pull request with a live, working URL
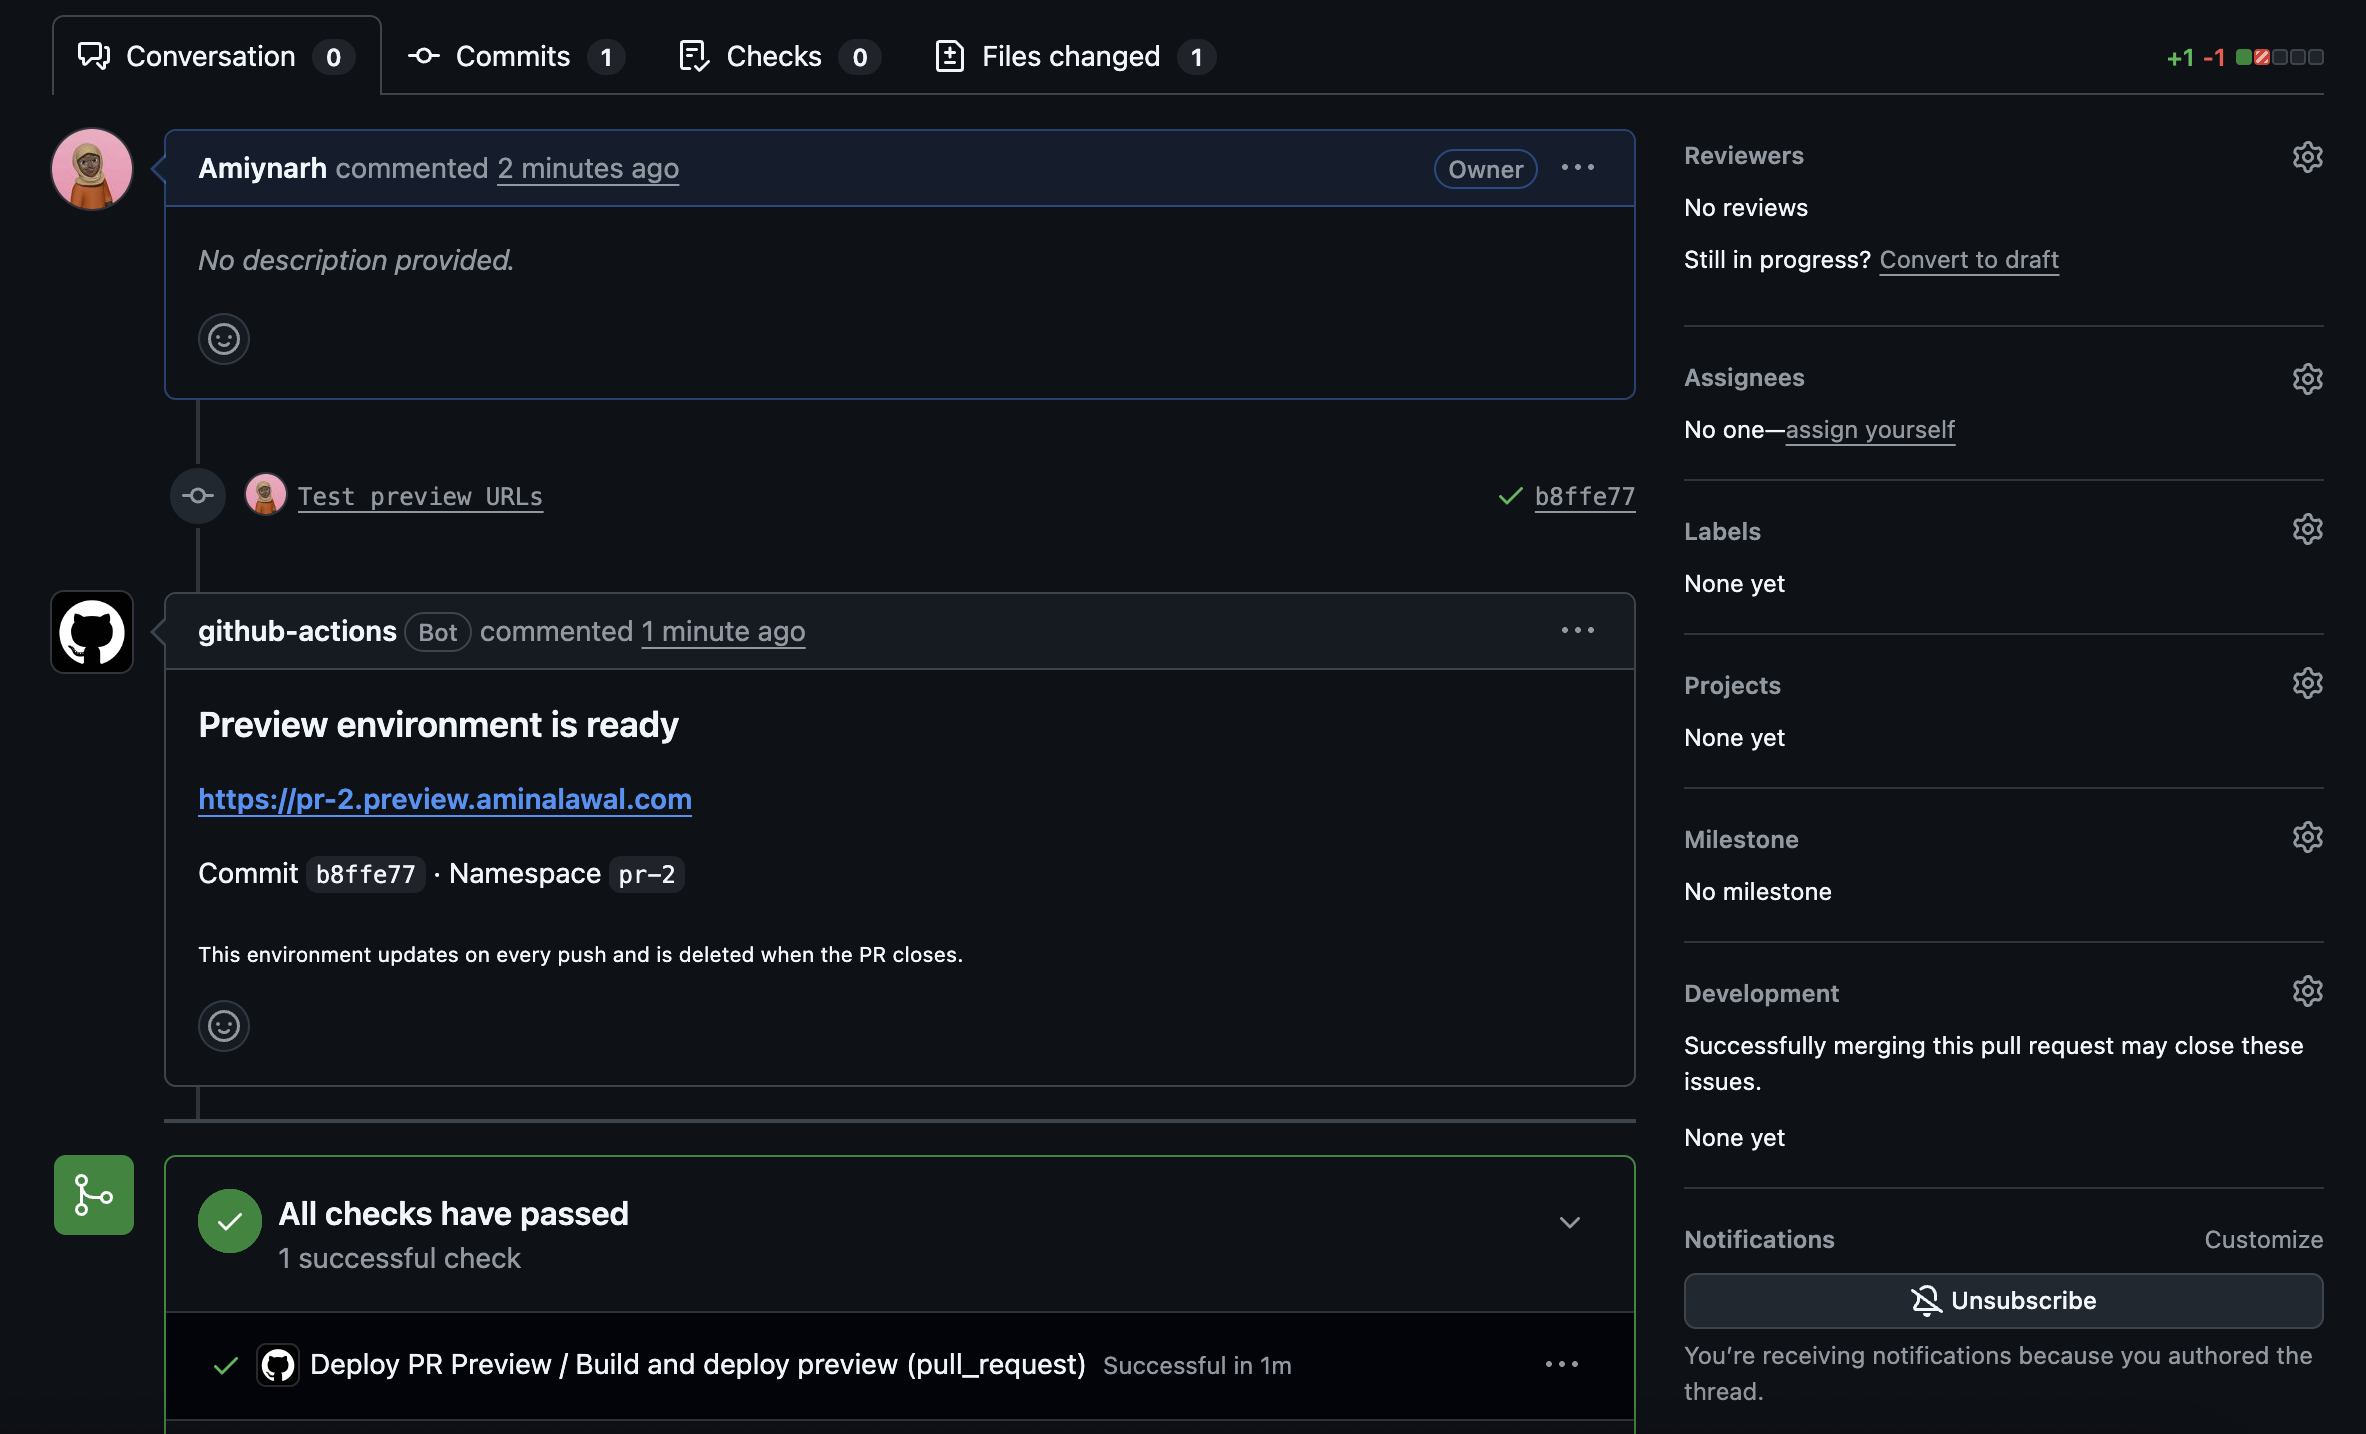
What You'll Build
By the end of this handbook, you'll have a working system where:
Opening a pull request triggers a GitHub Actions workflow that builds a container image tagged specifically for that PR
The image is pushed to Google Artifact Registry
A dedicated Kubernetes namespace (
pr-42,pr-43, and so on) is created inside a GKE cluster, with resource quotas applied before anything deploysThe application deploys into that namespace, completely isolated from every other PR's environment
A shared Ingress controller routes
pr-42.preview.yourdomain.comto that namespace, with a valid TLS certificate issued automaticallyA bot comments the live URL on the pull request, updating the same comment on every push
Pushing new commits redeploys the environment with the updated code
Closing or merging the PR deletes the namespace and everything inside it
A scheduled job catches any environment the teardown missed
You'll also build the underlying infrastructure with Terraform, with three key design decisions, each with its own section.
No service account keys: GitHub Actions authenticates to Google Cloud through Workload Identity Federation. Short-lived OIDC tokens verified against a repository claim. Service account JSON keys sitting in GitHub secrets are one of the most common security problems in CI/CD pipelines today, and you don't need one.
One load balancer, not one per PR: A single shared Ingress controller routes every environment by hostname, and one wildcard DNS record covers every hostname that will ever exist. The naïve version provisions a cloud load balancer per environment, which gets expensive quickly.
Cleanup that assumes failure: Teardown runs when a PR closes. But a scheduled reaper also deletes namespaces whose PR is gone or that have outlived a maximum age, because even 95% effective automated cleanup still leaks, and leaks show up on the bill.
Here's the architecture we're working toward:
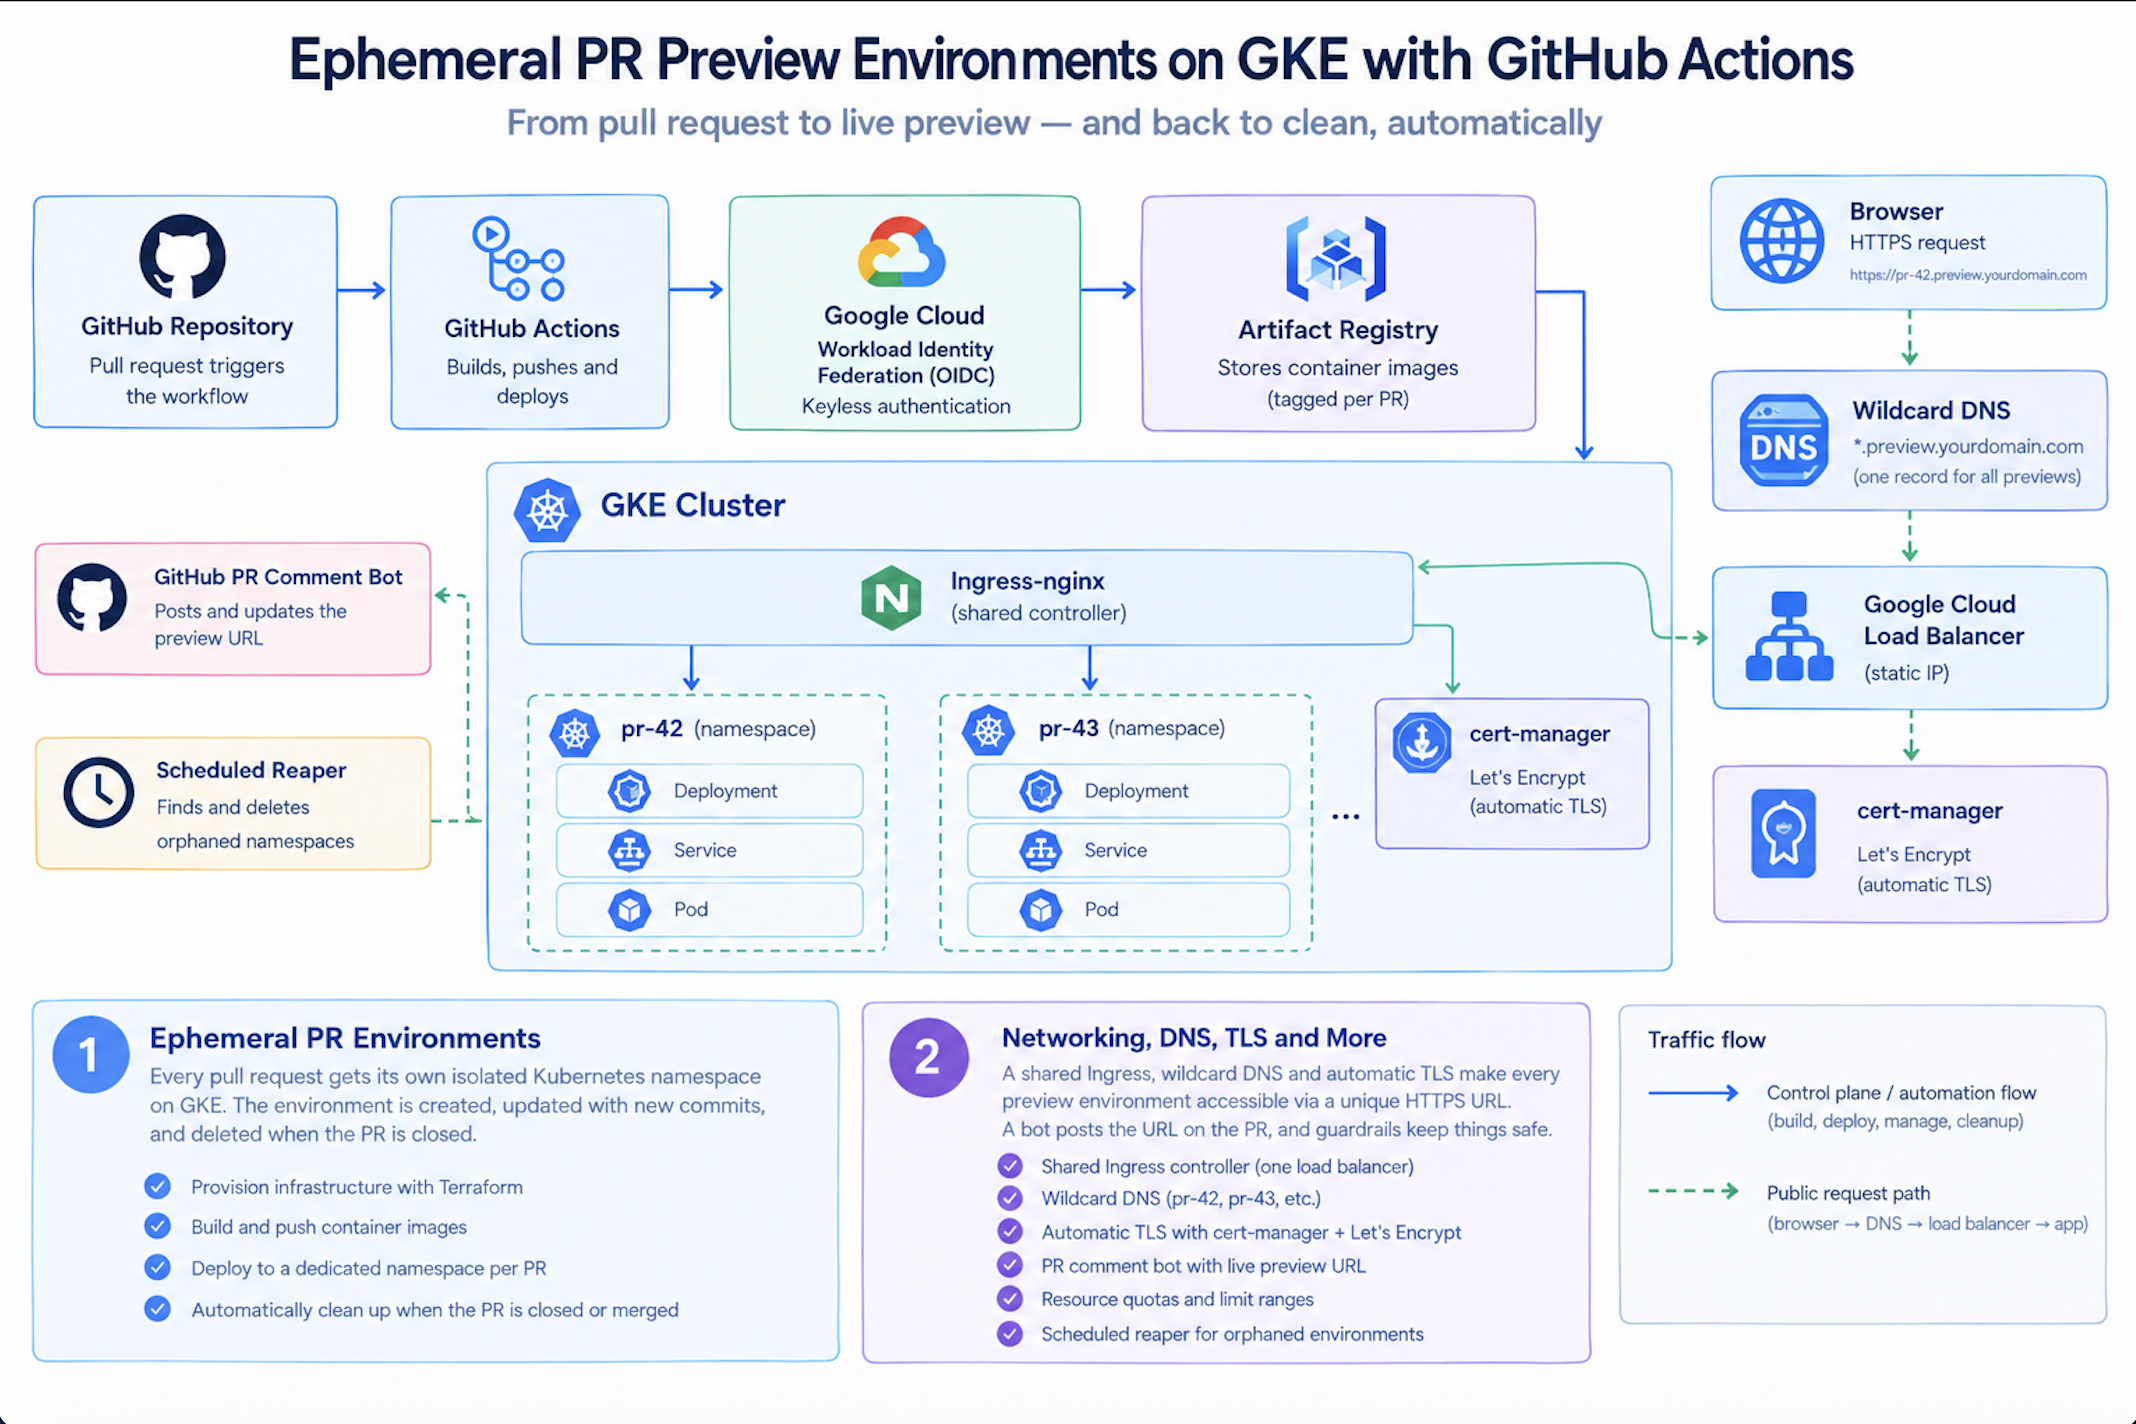
The diagram traces two separate paths through the same system.
The solid blue path is automation. A pull request triggers GitHub Actions, which authenticates to Google Cloud through Workload Identity Federation, pushes a PR-tagged image to Artifact Registry, and deploys into a dedicated namespace inside the GKE cluster.
Each namespace (pr-42, pr-43, and so on) holds its own Deployment, Service, and Pod, completely isolated from every other one.
Two more automated pieces sit alongside it: a bot that posts and updates the preview URL on the pull request, and a scheduled reaper that finds and deletes orphaned namespaces.
The dashed green path is public traffic. A browser request for a preview URL resolves through a single wildcard DNS record to one Google Cloud load balancer, which hands it to a shared NGINX Ingress controller. That controller reads the request's Host header and routes it to the right namespace. cert-manager runs beside it, requesting certificates from Let's Encrypt so each environment gets its own valid TLS certificate.
The important detail is what doesn't multiply. One load balancer, one DNS record, and one Ingress controller serve every environment, no matter how many pull requests are open.
Table of Contents
Prerequisites
Before you start, make sure you have the following ready:
A Google Cloud project with billing enabled. If you don't have one, create it at console.cloud.google.com. Running this tutorial costs roughly $5–10 depending on how long you leave the cluster up. Don't skip the cleanup section at the end.
gcloudCLI installed and authenticated. Rungcloud auth loginto sign in, andgcloud config set project YOUR_PROJECT_IDto point it at your project.Terraform version 1.5 or later. Check with
terraform version.kubectlinstalled. This is the CLI for interacting with Kubernetes clusters.Docker installed locally, for testing the build before you hand it to CI.
A GitHub repository that you own. This needs to be a repository you can push branches to and open pull requests against, since that's the trigger for everything we build.
Basic familiarity with Docker (images, layers, Dockerfile), Kubernetes (pods, deployments, services, namespaces), and GitHub Actions (workflows, jobs, steps). You don't need to be an expert, but you should know what these things are.
Helm version 3, for installing the Ingress controller and cert-manager. Check with
helm version.A domain name you control, with the ability to add DNS records. It doesn't matter where it's registered. You'll dedicate one subdomain to previews, like
preview.yourdomain.com, and every environment lives beneath it.
A note on the domain requirement: this is the part of the project that can't be faked. Let's Encrypt needs to verify that you control the domain before it will issue a certificate, and it verifies this by making a real HTTP request from the public internet. A .local domain, an entry in /etc/hosts, or a domain you don't own won't work.
If you don't have a spare domain, a .dev or .xyz costs a few pounds a year and is worth having for exactly this kind of project.
One more thing worth bringing your attention to early: you'll also need the gke-gcloud-auth-plugin. Recent versions of gcloud prompt you to install it the first time you connect to a GKE cluster. You can install it ahead of time with:
gcloud components install gke-gcloud-auth-plugin Step 1: Set Up the Project Structure
Let's lay out the directories first, so you have a clear mental model of where everything lives.
mkdir -p pr-preview-envs/{app,terraform,k8s/base,.github/workflows} cd pr-preview-envs git init Here's what each directory holds:
app/: the Go application and its Dockerfileterraform/: infrastructure as code: the GKE cluster, Artifact Registry, and Workload Identity Federation setupk8s/base/: the base Kubernetes manifests that every preview environment is built from.github/workflows/: the two GitHub Actions workflows that create and destroy environments
Connect this to a GitHub repository now, because the Workload Identity Federation setup in Step 5 needs to know your repository's full name (owner/repo):
git remote add origin https://github.com/YOUR_USERNAME/pr-preview-envs.git Step 2: Write the Application
We need something to deploy. We'll use Go, for three reasons that matter to this project specifically.
First, Go compiles to a single statically-linked binary. There's no runtime to install and no interpreter, which means very small container images, and small images mean fast pushes and fast pulls, which matters a lot when you're building an image on every single commit to every open PR.
Second, Go's -ldflags -X mechanism lets us inject values into the binary at build time. We'll use this to bake the PR number and Git commit SHA directly into the application, so the running app can tell us exactly which build it is.
And lastly, build times are fast, and CI minutes aren't free.
Create app/main.go:
package main import ( "fmt" "net/http" "os" ) // These values are empty at compile time and get injected by the // linker via -ldflags -X during the Docker build. See the Dockerfile. var ( prNumber = "local" gitSha = "dev" ) func handler(w http.ResponseWriter, r *http.Request) { // Kubernetes injects these via the Downward API — see deployment.yaml namespace := os.Getenv("POD_NAMESPACE") podName := os.Getenv("POD_NAME") if namespace == "" { namespace = "not-in-kubernetes" } if podName == "" { podName, _ = os.Hostname() } fmt.Fprintf(w, "Preview environment is live\n\n") fmt.Fprintf(w, "PR number : %s\n", prNumber) fmt.Fprintf(w, "Git SHA : %s\n", gitSha) fmt.Fprintf(w, "Namespace : %s\n", namespace) fmt.Fprintf(w, "Pod name : %s\n", podName) } func healthz(w http.ResponseWriter, r *http.Request) { w.WriteHeader(http.StatusOK) fmt.Fprintln(w, "ok") } func main() { http.HandleFunc("/", handler) http.HandleFunc("/healthz", healthz) fmt.Println("Server starting on port 8080...") if err := http.ListenAndServe(":8080", nil); err != nil { fmt.Fprintf(os.Stderr, "server error: %v\n", err) os.Exit(1) } } Initialize the Go module from inside app/:
cd app go mod init preview-app Let's walk through what this code does and why each piece is here.
var prNumber = "local" and var gitSha = "dev" are package-level string variables with default values. The defaults are what you'll see if you run the binary locally without going through the Docker build.
During the CI build, the Go linker overwrites them with the real PR number and commit SHA. This is the single most useful debugging feature in the whole project: when you hit a preview environment, the app itself tells you exactly which commit it was built from. There's no guessing.
os.Getenv("POD_NAMESPACE") and os.Getenv("POD_NAME") read environment variables that Kubernetes injects into the container using something called the Downward API. We'll configure that in the deployment manifest in Step 8.
The Downward API lets a pod read metadata about itself (its own name, namespace, and labels) without needing any Kubernetes API credentials. It's the cleanest way for an app to know where it's running.
The handler function is registered on the root path /. It writes the PR number, commit SHA, namespace, and pod name to the response. It's four pieces of information that together answer "what exactly am I looking at right now?"
The healthz function is registered on /healthz, and returns HTTP 200 with the text ok. Kubernetes uses this endpoint for liveness and readiness probes, which we'll wire up in the deployment manifest.
http.ListenAndServe(":8080", nil) starts the server on port 8080. If it fails to start, it prints the error and exits with a non-zero code, so Kubernetes knows the container is broken and can restart it.
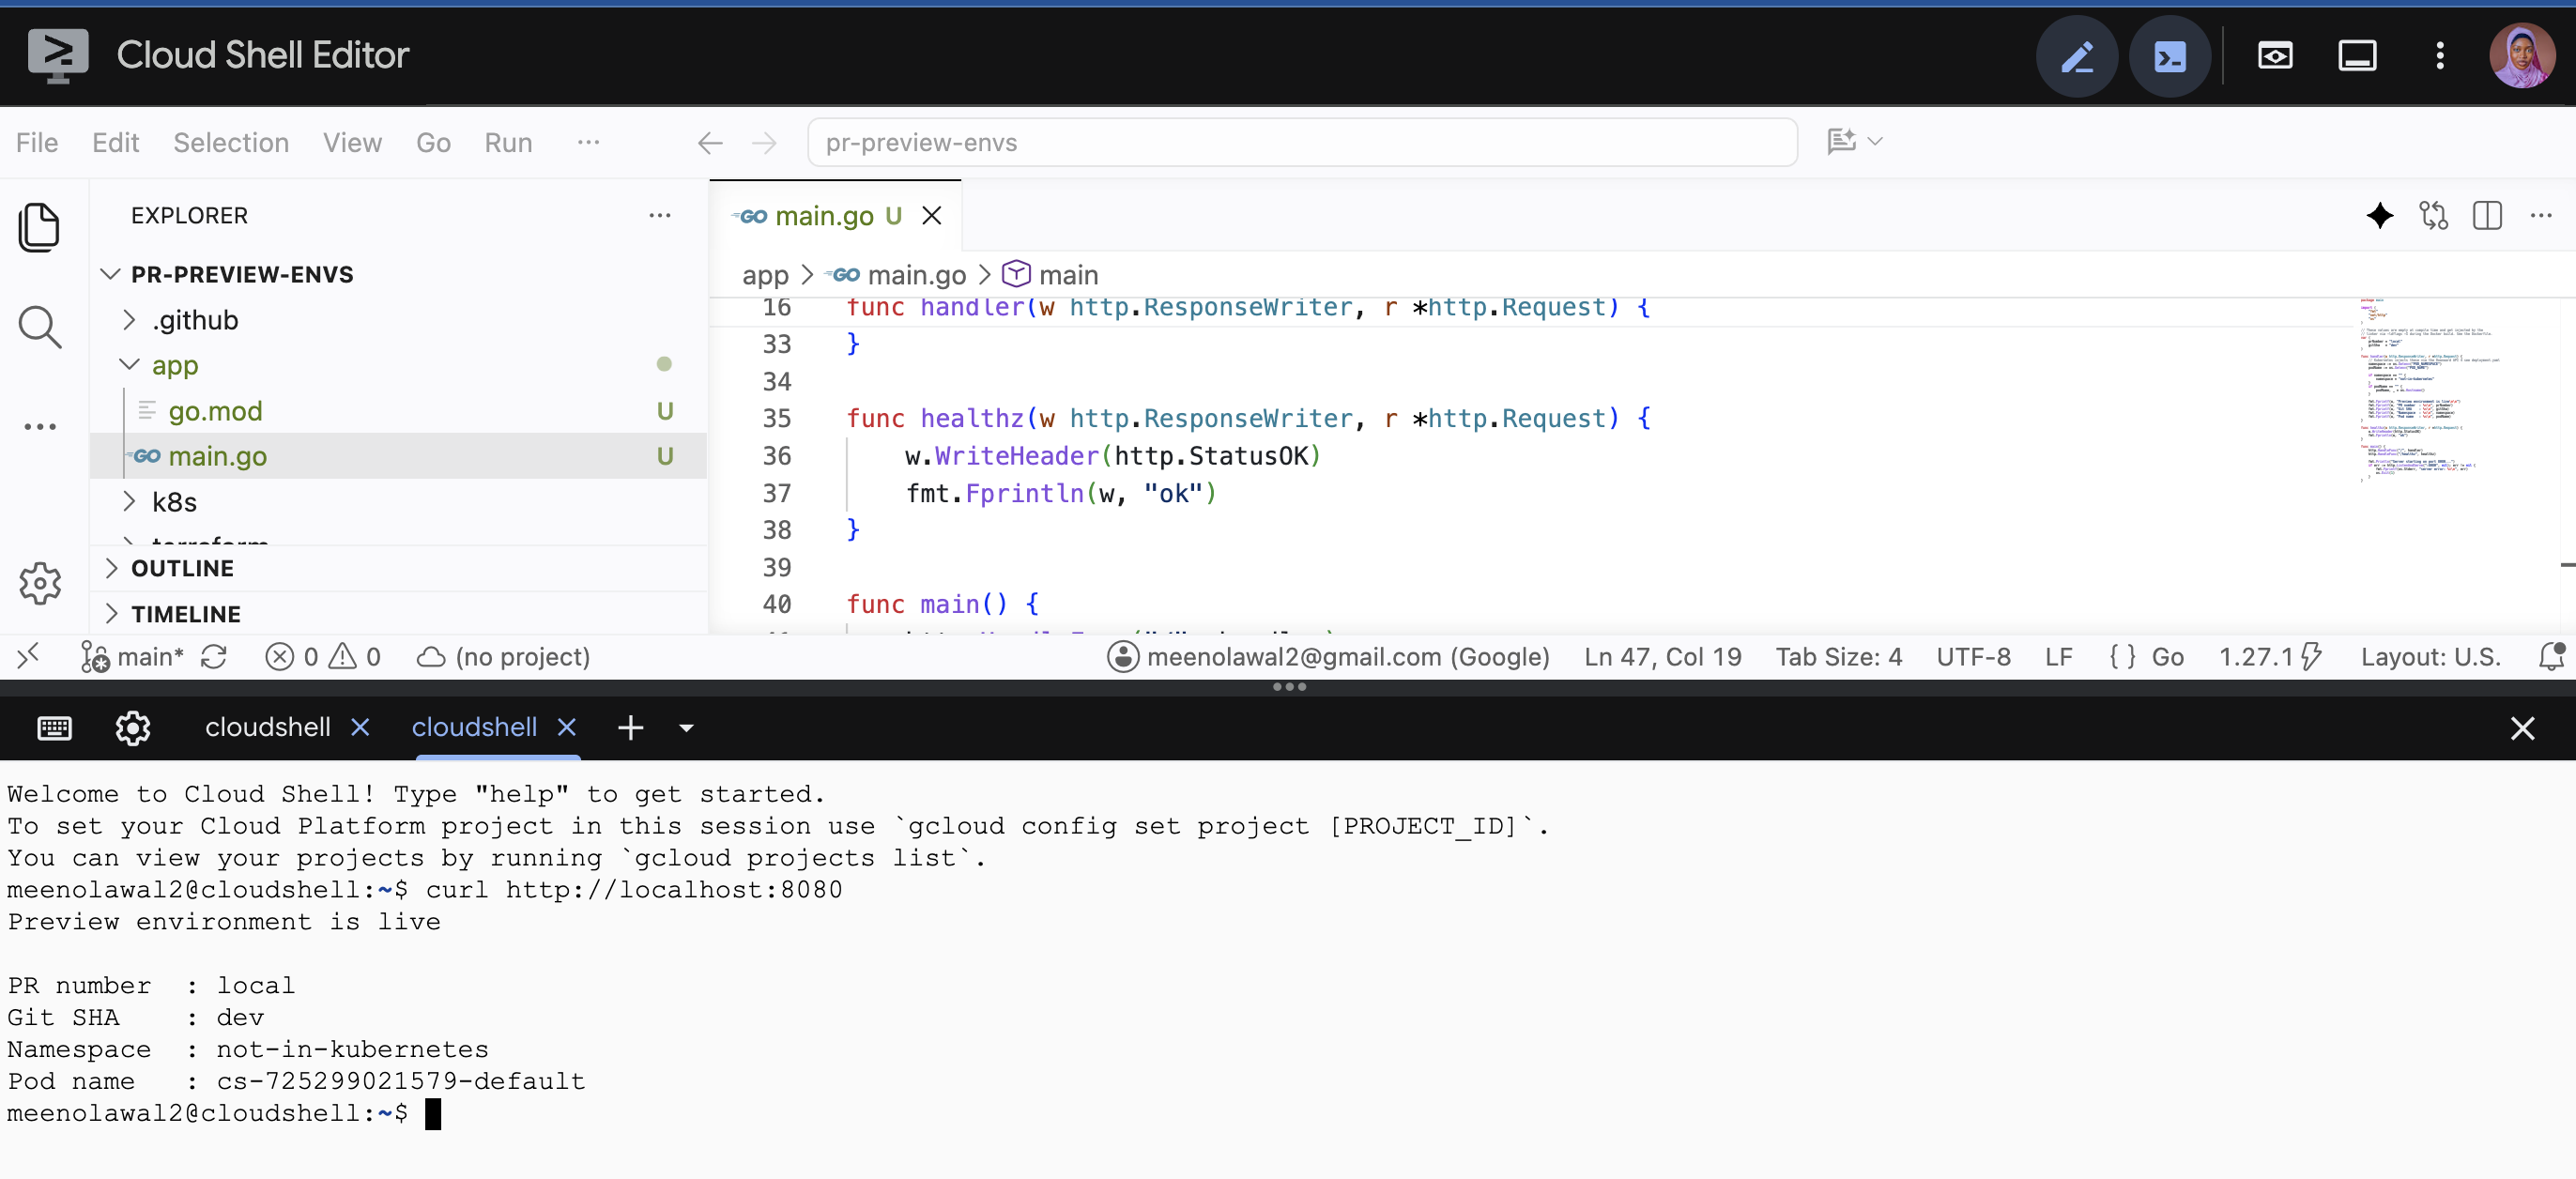
Test it locally before moving on:
go run main.go In a second terminal:
curl http://localhost:8080 You should see PR number : local and Git SHA : dev, since you're running outside the Docker build. That's the expected local behaviour.
Step 3: Write the Dockerfile
Create app/Dockerfile:
# ----------------------------------------------------------- # Stage 1: Build # ----------------------------------------------------------- FROM golang:1.27-alpine AS builder #Ensure the version matches what is in your go.mod file # These are injected by the CI pipeline at build time ARG PR_NUMBER=local ARG GIT_SHA=dev WORKDIR /app # Copy go.mod first so Docker can cache the dependency layer COPY go.mod . RUN go mod download COPY main.go . # -w -s strips debug symbols (~30% smaller binary) # -X overwrites package-level string variables at link time RUN CGO_ENABLED=0 go build \ -ldflags="-w -s -X main.prNumber=${PR_NUMBER} -X main.gitSha=${GIT_SHA}" \ -o server main.go # ----------------------------------------------------------- # Stage 2: Runtime # ----------------------------------------------------------- FROM alpine:latest RUN addgroup -S appgroup && adduser -S appuser -G appgroup USER appuser WORKDIR /app COPY --from=builder /app/server . EXPOSE 8080 CMD ["./server"] There are a few things happening here worth understanding properly.
1. The -ldflags -X Injection
-X main.prNumber=${PR_NUMBER} The -X linker flag sets the value of a package-level string variable at link time. The syntax is -X importpath.name=value. Since our variables live in package main, the import path is just main.
This only works on string variables that are already declared in the source. You can't create new variables this way, and you can't inject into an int or a bool. That's why prNumber is a string in main.go even though it holds a number.
Why do this instead of just passing an environment variable through the deployment manifest? Because build metadata belongs to the image, not the deployment. If you pass it as an env var, someone can deploy image abc123 with an env var claiming it's commit def456, and the app will happily lie to you. Baking it into the binary means the image can only ever report what it actually is.
The CGO_ENABLED=0 Flag
By default, Go can link against C libraries. When it does, the resulting binary depends on the system's C library being present at runtime. Alpine uses musl instead of the more common glibc, and that mismatch is a classic source of "works in the builder stage, crashes in the runtime stage" errors.
Setting CGO_ENABLED=0 forces a pure-Go, fully static binary with no external library dependencies. It will run on any Linux system, including a scratch image with nothing in it at all.
COPY go.mod . Before COPY main.go .
Docker builds images layer by layer and caches each layer. By copying only go.mod first and running go mod download before copying the source code, we create a cached dependency layer.
On subsequent builds (and remember, this pipeline builds on every commit to every open PR), Docker skips the dependency download entirely as long as go.mod hasn't changed. On a real project with dozens of dependencies, this is the difference between a 20-second build and a 3-minute build, multiplied by every push your team makes.
The Non-Root User
RUN addgroup -S appgroup && adduser -S appuser -G appgroup USER appuser Containers run as root by default. If an attacker finds a vulnerability in your application, running as root inside the container gives them significantly more room to escalate. Creating an unprivileged user and switching to it limits the blast radius. It costs you two lines, and there's no reason not to do it.
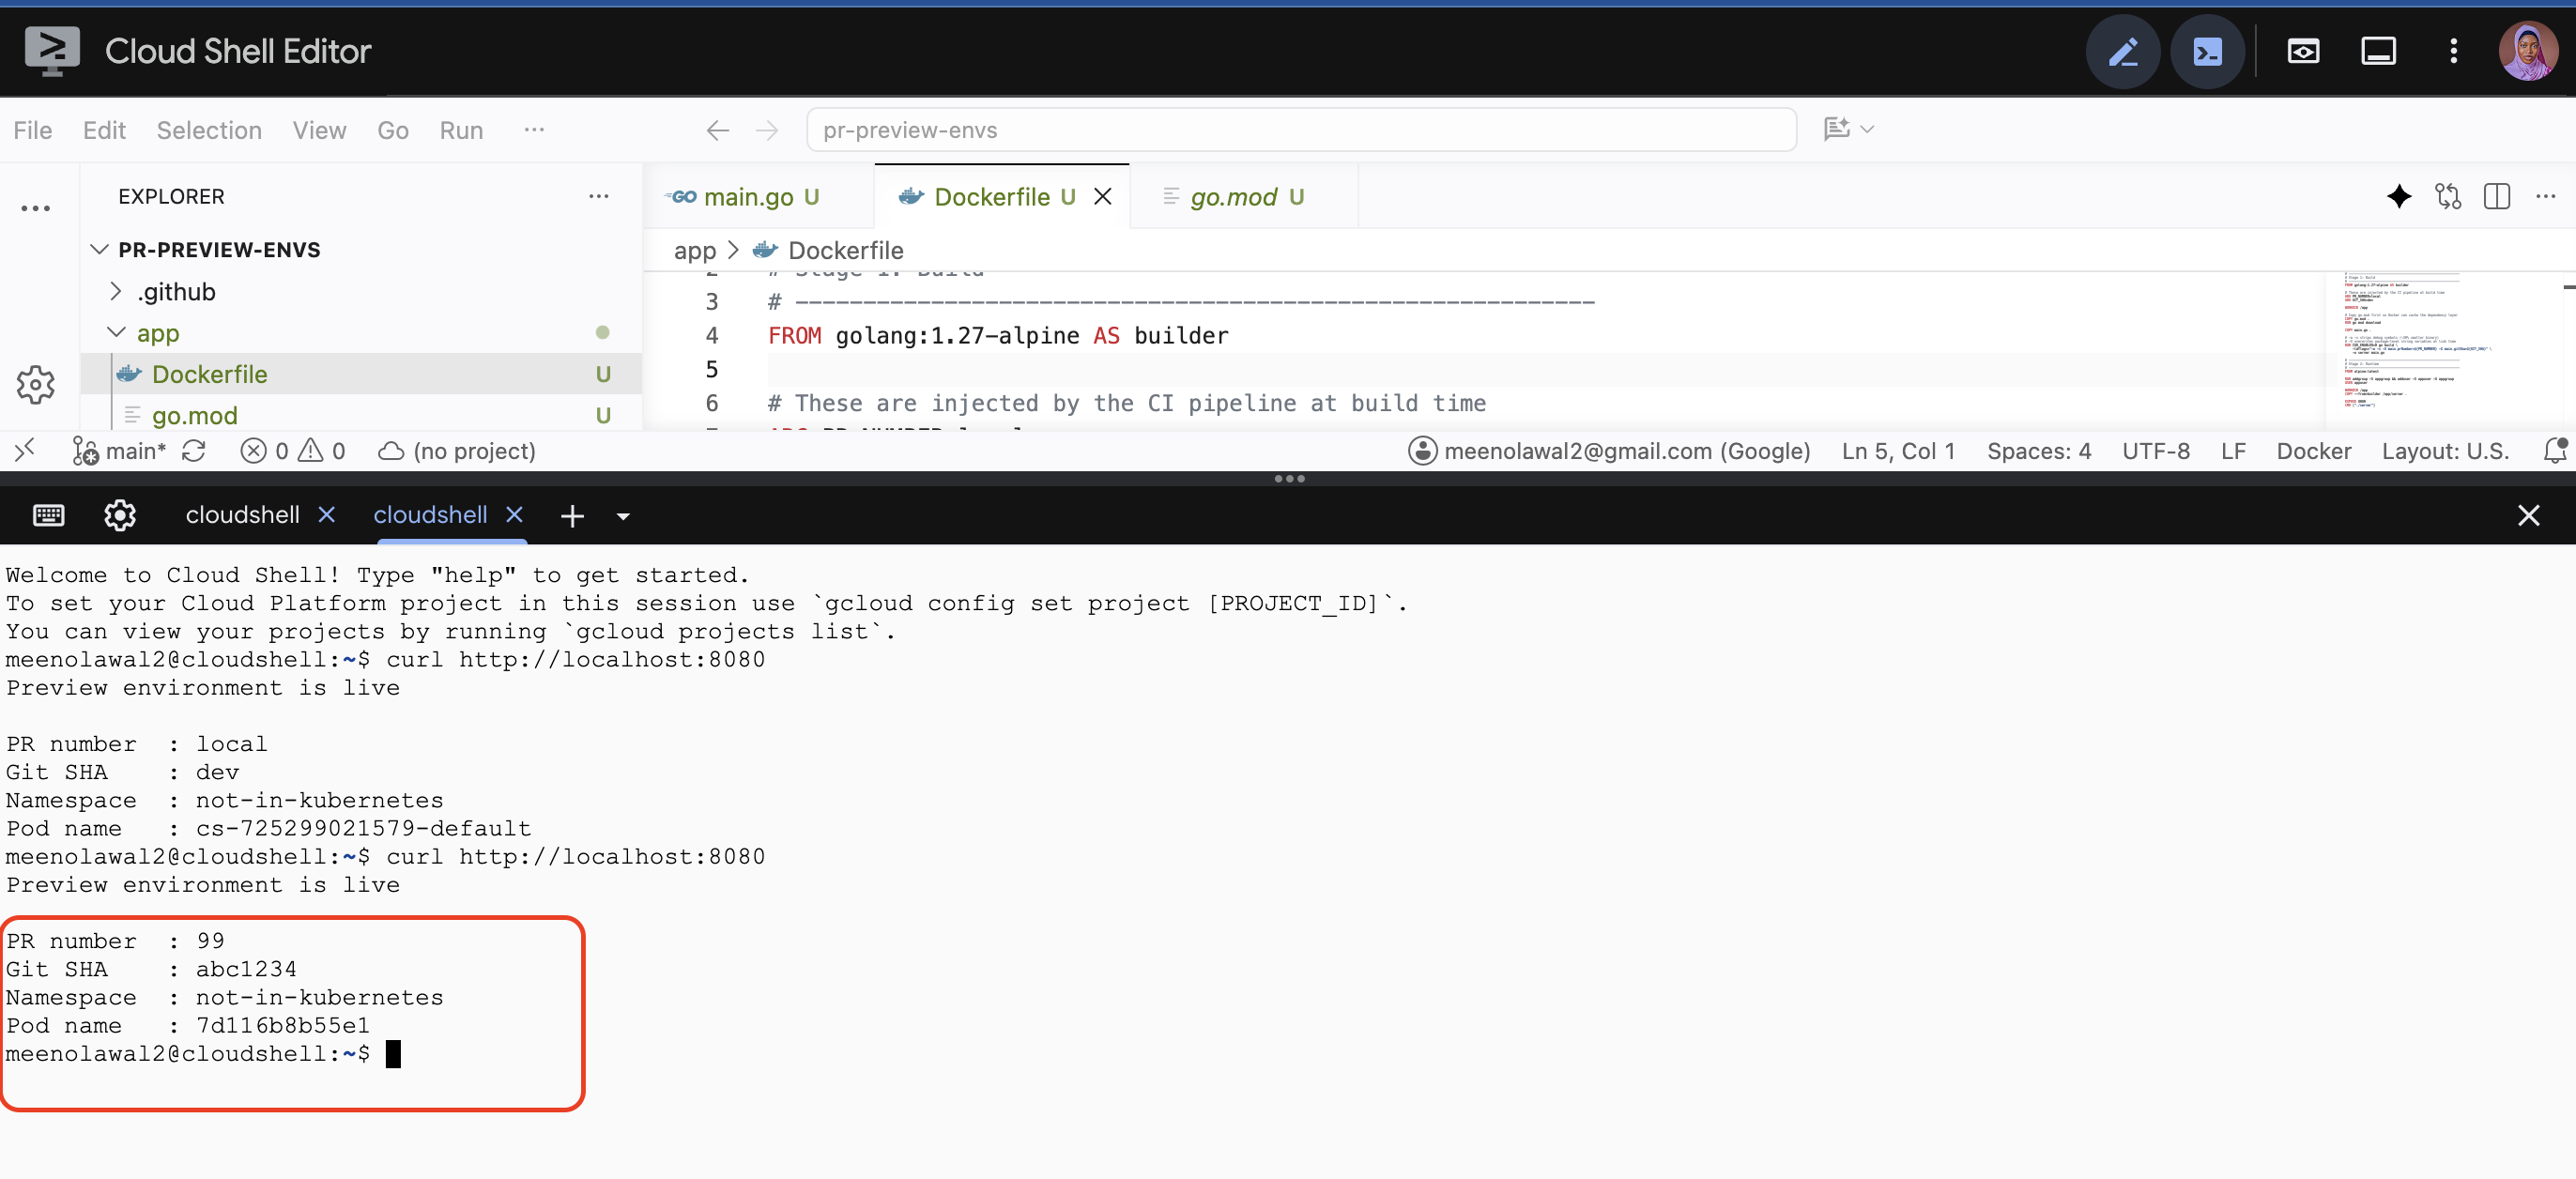
Build and test it locally:
docker build --build-arg PR_NUMBER=99 --build-arg GIT_SHA=abc1234 -t preview-app:test . docker run -p 8080:8080 preview-app:test Then curl http://localhost:8080 in another terminal. You should now see PR number : 99 and Git SHA : abc1234. The injection works.
Step 4: Provision the Infrastructure with Terraform
Now we'll build the cloud infrastructure. We're using Terraform rather than a series of gcloud commands for a reason that becomes obvious the moment something goes wrong: with Terraform, terraform destroy cleans up everything you created, in the right order, with no orphaned resources quietly billing you.
Create terraform/variables.tf:
variable "project_id" { description = "GCP project ID" type = string } variable "region" { description = "GCP region" type = string default = "europe-west2" } variable "zone" { description = "GCP zone. A zonal cluster is cheaper than a regional one." type = string default = "europe-west2-a" } variable "cluster_name" { description = "Name of the GKE cluster" type = string default = "pr-preview-cluster" } variable "github_repo" { description = "GitHub repository in owner/repo format, e.g. amina/pr-preview-envs" type = string } variable "machine_type" { description = "Node machine type" type = string default = "e2-standard-2" } variable "node_count" { description = "Number of nodes in the pool" type = number default = 2 } Now create terraform/main.tf:
terraform { required_version = ">= 1.5" required_providers { google = { source = "hashicorp/google" version = "~> 5.0" } } } provider "google" { project = var.project_id region = var.region } # Look up the project so we can reference its numeric project number, # which Workload Identity Federation requires (it doesn't accept the # human-readable project ID). data "google_project" "current" {} # ----------------------------------------------------------- # Enable required APIs # ----------------------------------------------------------- resource "google_project_service" "apis" { for_each = toset([ "container.googleapis.com", "artifactregistry.googleapis.com", "iamcredentials.googleapis.com", "sts.googleapis.com", ]) service = each.value disable_on_destroy = false } # ----------------------------------------------------------- # Artifact Registry — where preview images live # ----------------------------------------------------------- resource "google_artifact_registry_repository" "preview" { location = var.region repository_id = "pr-preview" description = "Container images for PR preview environments" format = "DOCKER" depends_on = [google_project_service.apis] } # ----------------------------------------------------------- # GKE cluster # ----------------------------------------------------------- resource "google_container_cluster" "primary" { name = var.cluster_name location = var.zone # Create the cluster with a throwaway default pool, then remove it # and manage nodes through a separate node pool resource. This is the # standard pattern — it lets you resize or upgrade the node pool # without recreating the cluster control plane. remove_default_node_pool = true initial_node_count = 1 networking_mode = "VPC_NATIVE" ip_allocation_policy {} # Set to true before you use this for anything real. deletion_protection = false depends_on = [google_project_service.apis] } resource "google_container_node_pool" "primary_nodes" { name = "${var.cluster_name}-pool" location = var.zone cluster = google_container_cluster.primary.name node_count = var.node_count node_config { machine_type = var.machine_type disk_size_gb = 50 oauth_scopes = [ "https://www.googleapis.com/auth/cloud-platform", ] labels = { purpose = "pr-preview-envs" } } management { auto_repair = true auto_upgrade = true } } There are a few things that're worth calling out here.
data "google_project" "current" isn't creating anything. It's a data source, which reads existing information from your provider. We need it because Workload Identity Federation identifies your project by its numeric project number, not the project ID you type in the console. Rather than making you look it up manually and paste it in, Terraform fetches it for you.
for_each on google_project_service: instead of writing four nearly identical resource blocks to enable four APIs, for_each iterates over a set and creates one resource per item. disable_on_destroy = false means terraform destroy won't turn these APIs off, which is what you want, because other things in your project might be using them.
remove_default_node_pool = true: GKE insists on creating a default node pool when you create a cluster. Setting this immediately deletes it, and we define our own node pool as a separate resource. The benefit is that node pool changes (resizing, changing machine type, upgrading) don't force a change to the cluster resource itself.
node_count = 2 with e2-standard-2: two nodes with 2 vCPU and 8GB each. Preview environments are small, but you'll have several running at once, plus GKE's own system pods. Two nodes give you comfortable headroom. If you plan to keep more than about eight preview environments alive simultaneously, bump this up.
deletion_protection = false: GKE added this as a guard against accidentally destroying production clusters. We're disabling it because this is a tutorial cluster you'll delete at the end. If you adapt this for real use, set it to true.
Step 5: Set Up Keyless Authentication with Workload Identity Federation
This is the section that matters most, so let's take it slowly.
The Problem With Service Account Keys
GitHub Actions needs permission to push images to Artifact Registry and deploy to your GKE cluster. The way most tutorials handle this is:
Create a service account in GCP
Generate a JSON key for it
Paste that JSON into a GitHub secret called
GCP_SA_KEYLoad it in the workflow
This works, but it's also a security problem, and here's why:
First, the key never expires. A service account JSON key is a long-lived credential. It's valid until someone explicitly revokes it, which in practice means it's valid forever, because nobody remembers to rotate them.
Second, the key is a bearer token. Anyone who obtains that JSON file is your service account. No second factor, IP restriction, or expiry. Copy the file, and use it from anywhere in the world.
Third, the blast radius is enormous. GitHub secrets are exposed to workflows. A compromised third-party action, a malicious dependency in your build, or a workflow modified in a pull request can exfiltrate that secret. Once it's out, an attacker has persistent access to your cloud project.
This isn't theoretical. Leaked service account keys are one of the most common root causes in cloud security incidents.
How Workload Identity Federation Fixes It
Workload Identity Federation removes the long-lived key entirely. Here's the flow:
GitHub Actions generates a short-lived OIDC token for the running workflow. This token is signed by GitHub and contains verified claims: which repository is running, which branch, which workflow, and which actor.
Your workflow presents that token to Google Cloud's Security Token Service.
Google checks the token's signature against GitHub's public keys, and checks the claims against rules you configured, specifically that the token came from your repository and no other.
If everything matches, Google issues a short-lived access token, typically valid for about an hour.
The workflow uses that token, and it expires shortly after.
There's no secret stored anywhere. Nothing to leak, rotate, or revoke. If someone forks your repository and runs the same workflow, the OIDC token they generate will carry their repository name in its claims, Google's check will fail, and they get nothing.
Add this to terraform/main.tf:
# ----------------------------------------------------------- # Service account that GitHub Actions will impersonate # ----------------------------------------------------------- resource "google_service_account" "github_actions" { account_id = "github-actions-preview" display_name = "GitHub Actions — PR Preview Environments" } # Permission to push images to Artifact Registry resource "google_project_iam_member" "artifact_writer" { project = var.project_id role = "roles/artifactregistry.writer" member = "serviceAccount:${google_service_account.github_actions.email}" } # Permission to create namespaces and deploy workloads in GKE. # container.developer grants full access to Kubernetes API objects, # but NOT permission to modify the cluster itself. resource "google_project_iam_member" "gke_developer" { project = var.project_id role = "roles/container.developer" member = "serviceAccount:${google_service_account.github_actions.email}" } # ----------------------------------------------------------- # Workload Identity Federation # ----------------------------------------------------------- resource "google_iam_workload_identity_pool" "github" { workload_identity_pool_id = "github-pool" display_name = "GitHub Actions Pool" description = "Identity pool for GitHub Actions OIDC" depends_on = [google_project_service.apis] } resource "google_iam_workload_identity_pool_provider" "github" { workload_identity_pool_id = google_iam_workload_identity_pool.github.workload_identity_pool_id workload_identity_pool_provider_id = "github-provider" display_name = "GitHub OIDC Provider" # Map claims from the GitHub OIDC token to Google attributes attribute_mapping = { "google.subject" = "assertion.sub" "attribute.actor" = "assertion.actor" "attribute.repository" = "assertion.repository" } # CRITICAL: without this condition, ANY GitHub repository on the # internet could authenticate against your pool. attribute_condition = "assertion.repository == '${var.github_repo}'" oidc { issuer_uri = "https://token.actions.githubusercontent.com" } } # Allow tokens from your specific repo to impersonate the service account resource "google_service_account_iam_member" "github_impersonation" { service_account_id = google_service_account.github_actions.name role = "roles/iam.workloadIdentityUser" member = "principalSet://iam.googleapis.com/projects/${data.google_project.current.number}/locations/global/workloadIdentityPools/${google_iam_workload_identity_pool.github.workload_identity_pool_id}/attribute.repository/${var.github_repo}" } Let's break down the parts that trip people up.
attribute_mapping: GitHub's OIDC token contains a set of claims. This block tells Google which claims to read and what to call them internally. assertion.sub is the token's subject (something like repo:owner/name:ref:refs/heads/main). assertion.repository is the full repository name. google.subject is required, while the others are optional attributes you can then write rules against.
attribute_condition: read this line twice, because getting it wrong is a serious vulnerability:
attribute_condition = "assertion.repository == '${var.github_repo}'" Without this condition, your identity pool trusts the GitHub OIDC issuer, which means it trusts every repository on GitHub. Anyone who knows your pool's resource path (which isn't secret and appears in workflow files) could authenticate and impersonate your service account.
This condition narrows the trust to exactly one repository. Google now requires an attribute condition when you map assertion.repository, precisely because so many people got this wrong.
principalSet://...: this is the identity being granted the workloadIdentityUser role. Read it right to left: any principal in the github-pool whose attribute.repository equals your repo may impersonate this service account. Note that it uses data.google_project.current.number, which is the numeric project number, not the project ID. Using the project ID here produces an error that doesn't clearly explain what's wrong, and it's one of the most common mistakes with WIF.
Why roles/container.developer and not roles/container.admin? container.developer grants full access to Kubernetes API objects inside clusters: creating namespaces, applying deployments, deleting resources. container.admin additionally allows modifying the clusters themselves: resizing node pools, upgrading, deleting the cluster entirely.
Our workflow never needs to touch the cluster's own configuration, so it shouldn't have permission to. This is least privilege in practice: grant exactly what the job requires and nothing beyond it.
Now create terraform/outputs.tf:
output "cluster_name" { value = google_container_cluster.primary.name } output "cluster_zone" { value = var.zone } output "artifact_registry_url" { description = "Base URL for pushing images" value = "${var.region}-docker.pkg.dev/${var.project_id}/${google_artifact_registry_repository.preview.repository_id}" } output "workload_identity_provider" { description = "Paste this into the GitHub Actions workflow" value = "projects/${data.google_project.current.number}/locations/global/workloadIdentityPools/${google_iam_workload_identity_pool.github.workload_identity_pool_id}/providers/${google_iam_workload_identity_pool_provider.github.workload_identity_pool_provider_id}" } output "service_account_email" { description = "Paste this into the GitHub Actions workflow" value = google_service_account.github_actions.email } output "get_credentials_command" { value = "gcloud container clusters get-credentials ${google_container_cluster.primary.name} --zone ${var.zone} --project ${var.project_id}" } Those outputs aren't decoration. workload_identity_provider and service_account_email are the two values you'll paste into your GitHub Actions workflow, and both are tedious to construct by hand.
Step 6: Apply the Terraform Configuration
From inside the terraform/ directory:
terraform init This downloads the Google provider and sets up the backend. You should see "Terraform has been successfully initialized!"
Now preview what will be created:
terraform plan \ -var="project_id=YOUR_PROJECT_ID" \ -var="github_repo=YOUR_USERNAME/pr-preview-envs" Read the plan output. Terraform tells you exactly what it intends to create before it creates anything. You should see roughly a dozen resources to add and none to change or destroy.
If that looks right:
terraform apply \ -var="project_id=YOUR_PROJECT_ID" \ -var="github_repo=YOUR_USERNAME/pr-preview-envs" Type yes when prompted. Cluster creation takes about five minutes.
Tip: typing those -var flags repeatedly gets old fast. Create a file called terraform.tfvars containing project_id = "your-project-id" and github_repo = "you/pr-preview-envs", and Terraform picks it up automatically. Add it to .gitignore.
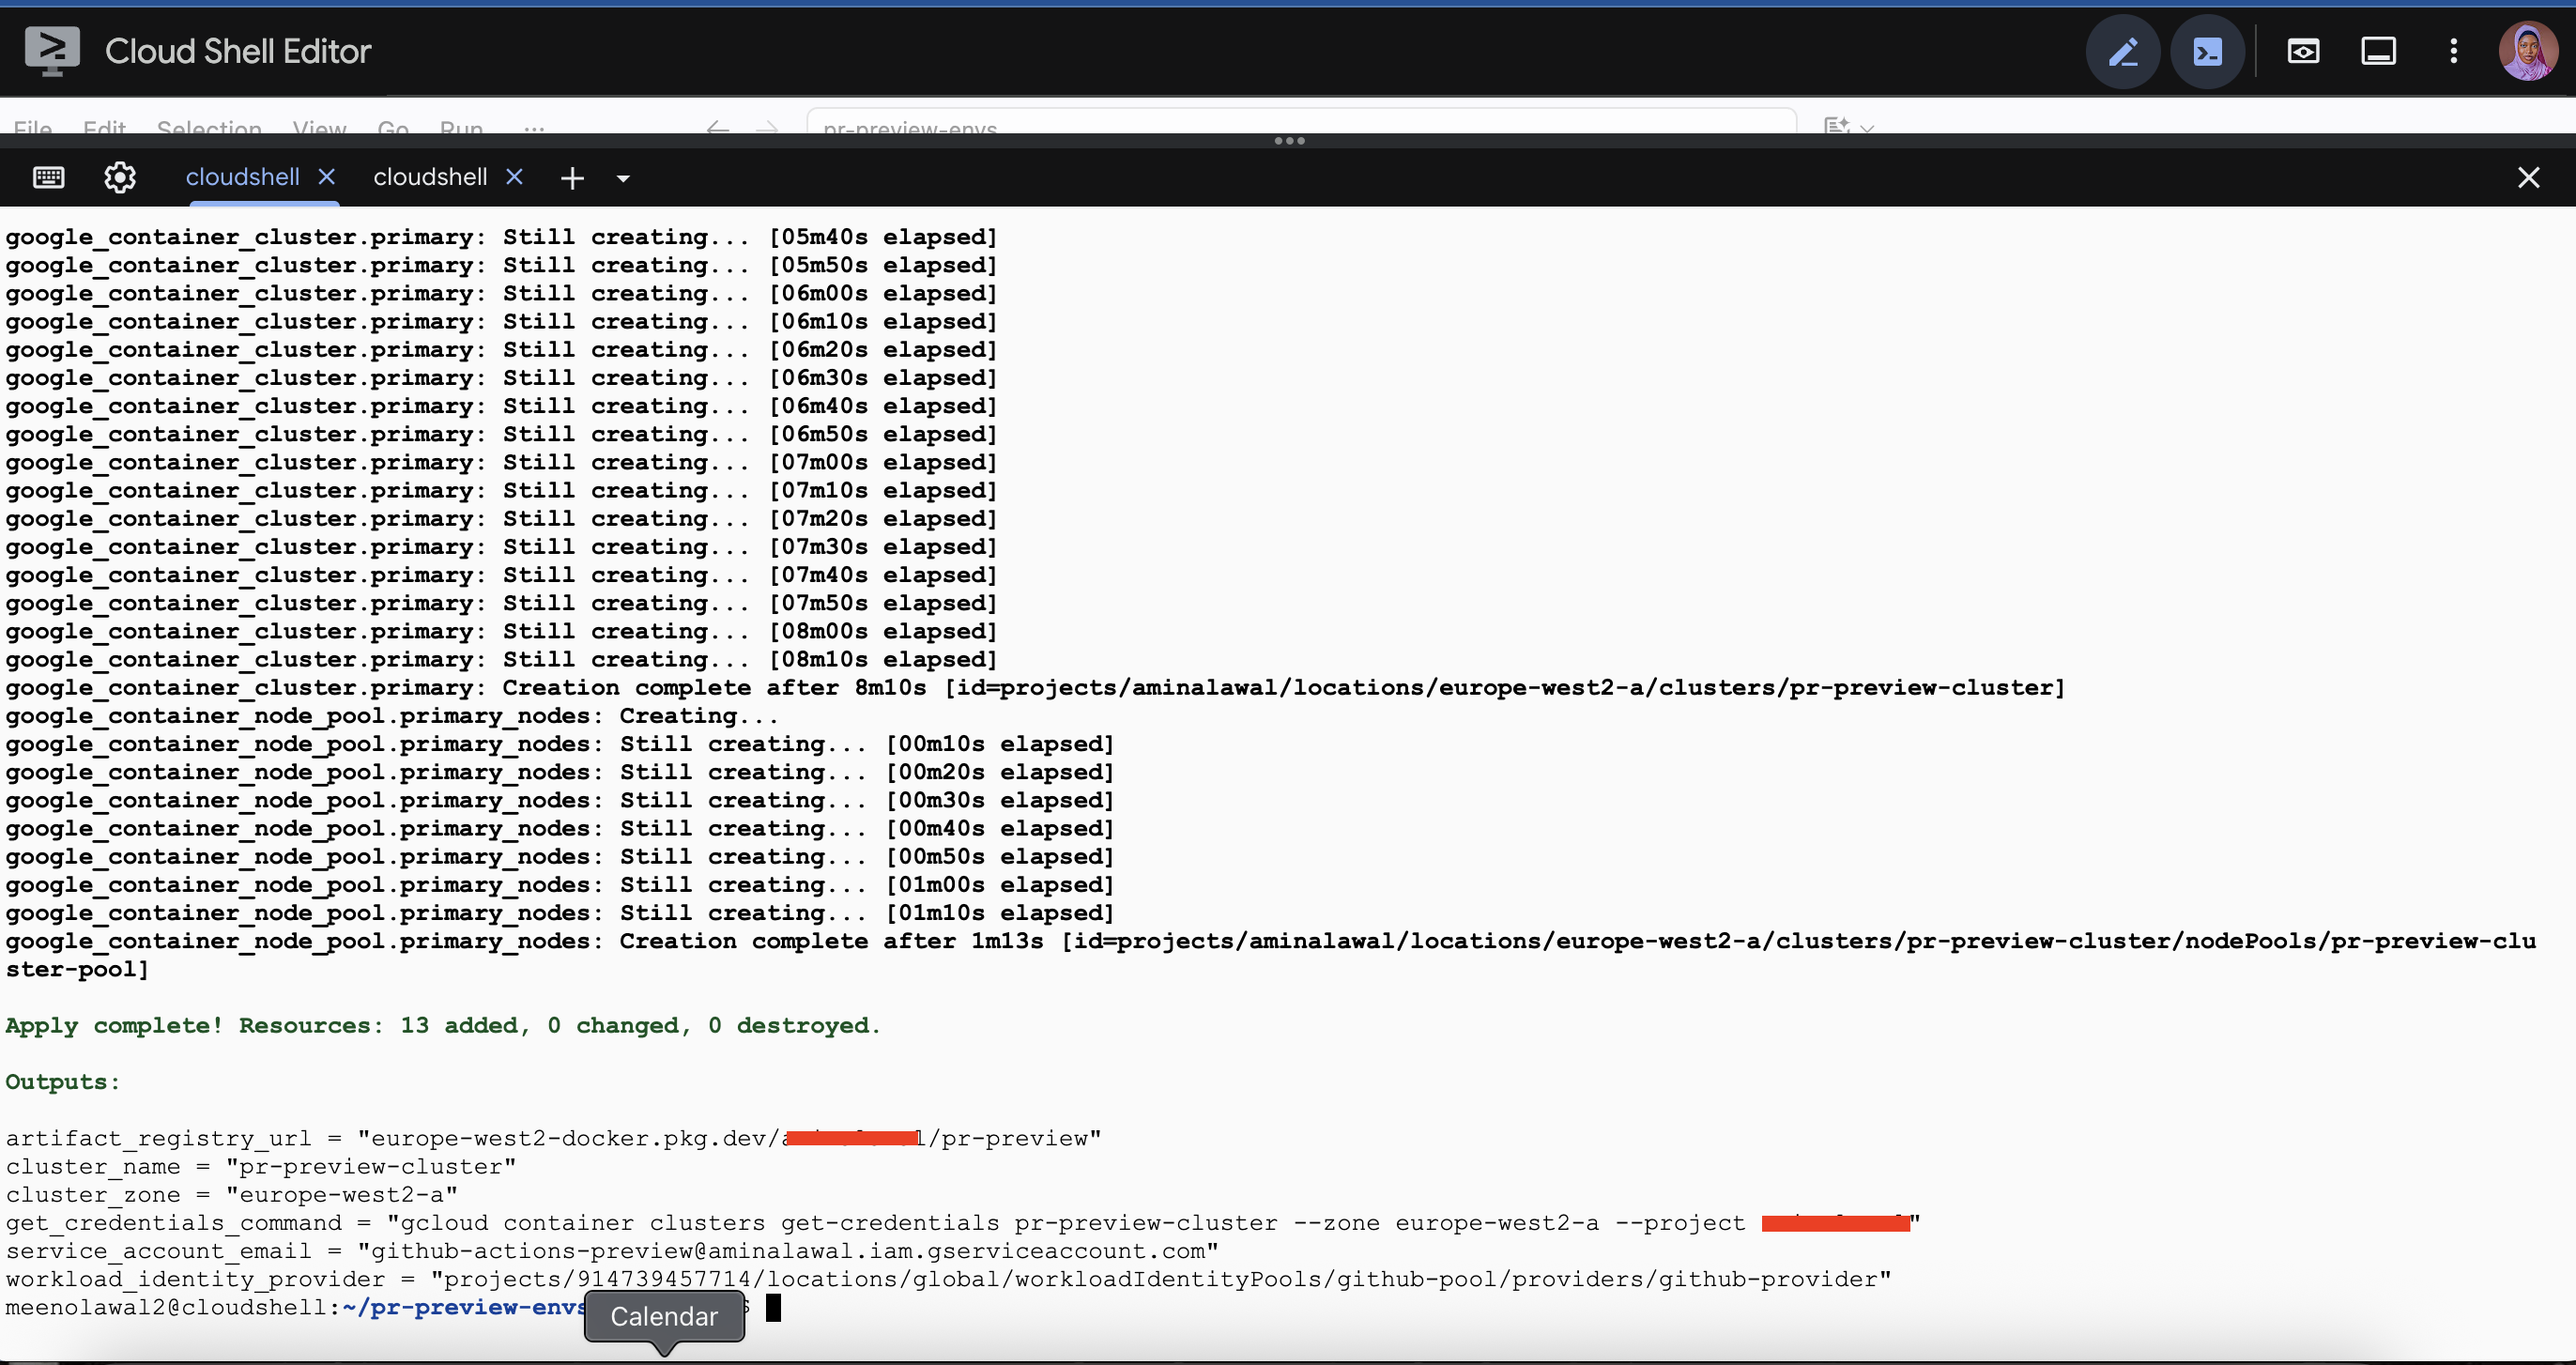
When it finishes, Terraform prints your outputs. Save these, as you'll need them in Step 9:
artifact_registry_url = "europe-west2-docker.pkg.dev/your-project/pr-preview" service_account_email = "github-actions-preview@your-project.iam.gserviceaccount.com" workload_identity_provider = "projects/123456789/locations/global/workloadIdentityPools/github-pool/providers/github-provider" You can print them again any time with terraform output.
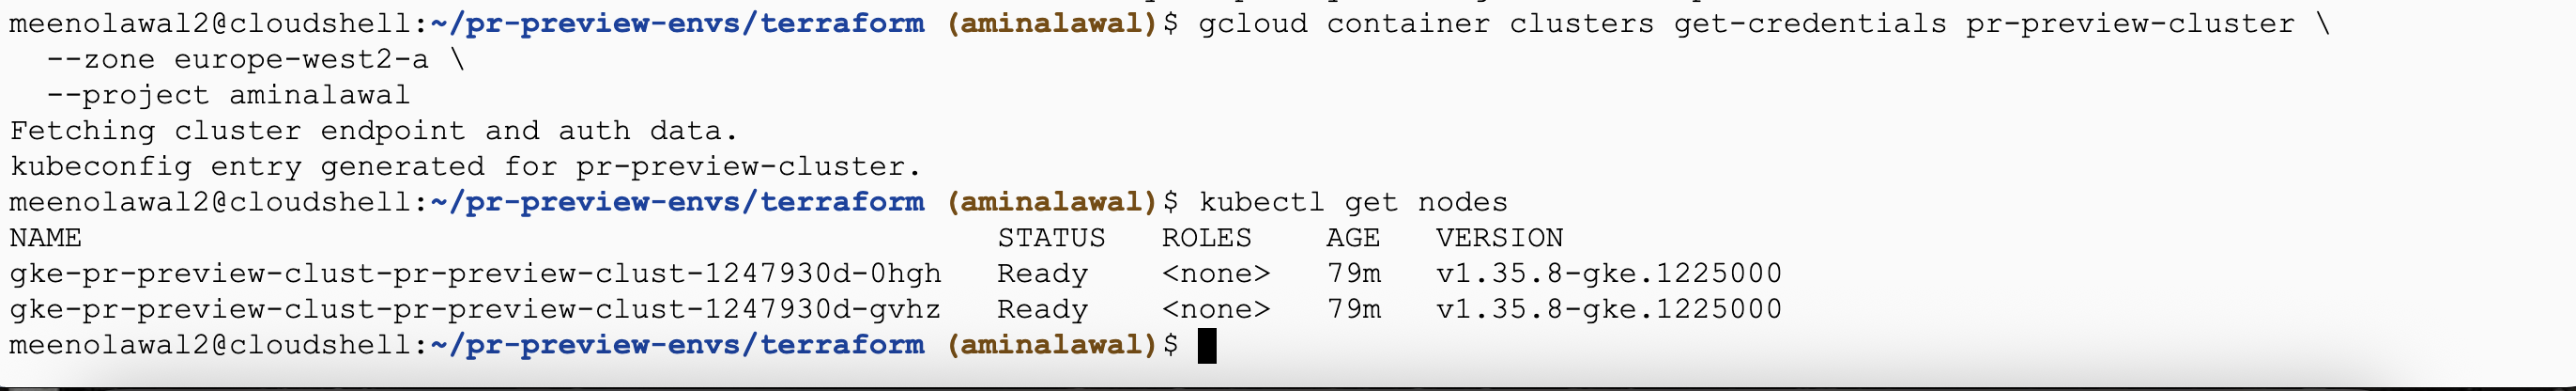
Connect kubectl to the new cluster using the command from the get_credentials_command output:
gcloud container clusters get-credentials pr-preview-cluster \ --zone europe-west2-a \ --project YOUR_PROJECT_ID Verify:
kubectl get nodes You should see two nodes in Ready state.
Step 7: Prove the Lifecycle Manually
Before automating anything, do it by hand once.
This isn't busywork. Automation is fundamentally just a script running commands you could have typed. If you don't know what the commands are, you can't debug the automation when it fails...and it will fail, usually at 11 pm before a demo. Ten minutes here saves hours later.
Create a namespace:
kubectl create namespace pr-test Deploy a placeholder into it:
kubectl create deployment hello \ --image=nginx:1.27-alpine \ --namespace=pr-test Check it:
kubectl get pods --namespace=pr-test Now the important part – prove the isolation:
kubectl get pods --all-namespaces | grep hello The pod exists only in pr-test. Nothing in default or any other namespace knows about it. That's the property the entire project is built on: a namespace is a boundary, and everything inside one PR's namespace is invisible to every other.
Now tear it down:
kubectl delete namespace pr-test Watch what happens:
kubectl get namespace pr-test For a few seconds, you'll see Terminating, then the namespace disappears entirely. Deleting a namespace deletes every resource inside it: deployments, pods, services, config maps, secrets, everything. One command, complete cleanup.
That single property is why namespace-per-PR is such a good fit for preview environments. Teardown isn't a careful sequence of deletions you have to get right. It's one command that can't leave anything behind.
Step 8: Write the Kubernetes Manifests with Kustomize
Every preview environment deploys the same application. The only differences between pr-42 and pr-43 are the namespace and the image tag.
This is exactly the problem Kustomize solves. You write the manifests once as a base, then apply small, declarative changes on top of it (an overlay) without templating, string substitution, or sed scripts mangling your YAML.
Kustomize is built into kubectl (that's the -k flag), so there's nothing extra to install.
Create k8s/base/deployment.yaml:
apiVersion: apps/v1 kind: Deployment metadata: name: preview-app labels: app: preview-app spec: replicas: 1 selector: matchLabels: app: preview-app template: metadata: labels: app: preview-app spec: containers: - name: preview-app # This is a placeholder. The overlay replaces it with the # real registry path and PR-specific tag. image: preview-app ports: - containerPort: 8080 env: # Downward API: the pod learns its own identity - name: POD_NAMESPACE valueFrom: fieldRef: fieldPath: metadata.namespace - name: POD_NAME valueFrom: fieldRef: fieldPath: metadata.name livenessProbe: httpGet: path: /healthz port: 8080 initialDelaySeconds: 5 periodSeconds: 10 readinessProbe: httpGet: path: /healthz port: 8080 initialDelaySeconds: 2 periodSeconds: 5 resources: requests: cpu: "50m" memory: "64Mi" limits: cpu: "200m" memory: "128Mi" Create k8s/base/service.yaml:
apiVersion: v1 kind: Service metadata: name: preview-app spec: selector: app: preview-app ports: - protocol: TCP port: 80 targetPort: 8080 type: ClusterIP Create k8s/base/kustomization.yaml:
apiVersion: kustomize.config.k8s.io/v1beta1 kind: Kustomization resources: - deployment.yaml - service.yaml There are some deliberate choices here.
replicas: 1: production runs multiple replicas for availability. A preview environment doesn't need high availability. One replica per environment, multiplied across every open PR, keeps your node count and your bill sane.
image: preview-app: a bare placeholder with no registry and no tag. It would never pull as-is. Kustomize's image transformer matches on this name and replaces it wholesale, so the base manifest never needs to know your registry URL.
The Downward API env block: this is where POD_NAMESPACE and POD_NAME come from. fieldRef reads a field from the pod's own spec at runtime and exposes it as an environment variable. No API calls, credentials, or service account needed.
type: ClusterIP: internal-only. Each LoadBalancer service provisions a real Google Cloud load balancer with a real hourly cost and a public IP. Doing that per PR would be expensive and wasteful. We'll reach the app with kubectl port-forward for now, and in Step 13 a single shared Ingress controller takes over, serving every environment through one load balancer.
Resource requests and limits: requests reserve capacity so the scheduler knows how much room a pod needs. limits cap what it can consume. Without limits, one runaway preview environment could starve every other one on the node. With many short-lived environments coming and going, this isn't optional.
Test the base renders correctly:
kubectl kustomize k8s/base That prints the rendered YAML without applying it. This is useful for debugging.
Step 9: Build the Spin-Up Workflow
Now we connect everything.
Create .github/workflows/preview-deploy.yml:
name: Deploy PR Preview on: pull_request: types: [opened, synchronize, reopened] # If someone pushes three commits quickly, cancel the older runs. # Without this, three deploys race each other into the same namespace # and whichever finishes last wins — which may not be the newest commit. concurrency: group: preview-${{ github.event.pull_request.number }} cancel-in-progress: true permissions: contents: read id-token: write # REQUIRED for Workload Identity Federation pull-requests: write env: PROJECT_ID: YOUR_PROJECT_ID REGION: europe-west2 CLUSTER_NAME: pr-preview-cluster CLUSTER_ZONE: europe-west2-a REPOSITORY: pr-preview IMAGE_NAME: preview-app jobs: deploy: name: Build and deploy preview runs-on: ubuntu-latest steps: - name: Check out code uses: actions/checkout@v4 - name: Set environment variables run: | PR_NUMBER=${{ github.event.pull_request.number }} SHORT_SHA=$(echo "${{ github.event.pull_request.head.sha }}" | cut -c1-7) echo "PR_NUMBER=${PR_NUMBER}" >> $GITHUB_ENV echo "SHORT_SHA=${SHORT_SHA}" >> $GITHUB_ENV echo "NAMESPACE=pr-${PR_NUMBER}" >> $GITHUB_ENV echo "IMAGE_TAG=pr-${PR_NUMBER}-${SHORT_SHA}" >> $GITHUB_ENV echo "IMAGE_BASE=${{ env.REGION }}-docker.pkg.dev/${{ env.PROJECT_ID }}/${{ env.REPOSITORY }}/${{ env.IMAGE_NAME }}" >> $GITHUB_ENV - name: Authenticate to Google Cloud uses: google-github-actions/auth@v2 with: workload_identity_provider: ${{ secrets.WIF_PROVIDER }} service_account: ${{ secrets.WIF_SERVICE_ACCOUNT }} - name: Set up gcloud uses: google-github-actions/setup-gcloud@v2 - name: Configure Docker for Artifact Registry run: gcloud auth configure-docker ${{ env.REGION }}-docker.pkg.dev --quiet - name: Build and push image run: | docker build \ --build-arg PR_NUMBER="${PR_NUMBER}" \ --build-arg GIT_SHA="${SHORT_SHA}" \ -t "${IMAGE_BASE}:${IMAGE_TAG}" \ ./app docker push "${IMAGE_BASE}:${IMAGE_TAG}" - name: Get GKE credentials uses: google-github-actions/get-gke-credentials@v2 with: cluster_name: ${{ env.CLUSTER_NAME }} location: ${{ env.CLUSTER_ZONE }} - name: Create namespace run: | # --dry-run=client | apply makes this idempotent. # Running it on an existing namespace is a no-op, not an error. kubectl create namespace "${NAMESPACE}" \ --dry-run=client -o yaml | kubectl apply -f - - name: Generate Kustomize overlay run: | mkdir -p k8s/overlays/"${NAMESPACE}" cat > k8s/overlays/"${NAMESPACE}"/kustomization.yaml <<EOF apiVersion: kustomize.config.k8s.io/v1beta1 kind: Kustomization namespace: ${NAMESPACE} resources: - ../../base images: - name: preview-app newName: ${IMAGE_BASE} newTag: ${IMAGE_TAG} EOF echo "--- Rendered manifest ---" kubectl kustomize k8s/overlays/"${NAMESPACE}" - name: Deploy run: kubectl apply -k k8s/overlays/"${NAMESPACE}" - name: Wait for rollout run: | kubectl rollout status deployment/preview-app \ --namespace="${NAMESPACE}" \ --timeout=180s - name: Show deployment details run: | echo "Namespace: ${NAMESPACE}" kubectl get pods,svc --namespace="${NAMESPACE}" Add the Two Secrets
Go to your repository on GitHub and go to Settings, Secrets and variables, Actions, and New repository secret. Add:


