AI & ML
MuseFlow-TSE: Music-Aware Target Speech Extraction via Cross-Source Band-Splitting and Data-to-Data Flow Matching
arXiv cs.SD0 views
arXiv:2610.29119v1 Announce Type: new Abstract: Target speech extraction (TSE) isolates a speaker's voice given an enrollment utterance, but existing work is validated almost exclusively without music. Discriminative methods are content-faithful yet masking-bounded; generative methods improve naturalness but may hallucinate, drift in identity, and require many steps. We present MuseFlow-TSE, a discriminative deletion, generative insertion framework for music-bearing scenes. Stage-1 is a music-aware cross-source band-split extractor that estimates target, interfering speakers, music, and noise under conservation and music-leakage constraints. Stage-2 is a data-to-data flow refiner initialized by the discriminative estimate, negatively conditioned on interference stems, and run for 1--4 difficulty-adaptive Euler steps with an end-to-end fidelity objective.
Source:https://arxiv.org/abs/2610.29119PreviousDual-Channel Contrastive Encoding of Sperm Whale CodaNextCharacter-Level Prosody Control for Mandarin Speech Synthesis:An Architecture-Preserving Approach
Related posts

HR manager LinkedIn About section examples you can adapt
0dev.to Career

🚀 Ready to explore the world of AWS Cloud and build something amazing together? ☁️
0dev.to Programming

The Second Scrape Should Be Almost Free
0dev.to Programming

Updates to Authtics Advisories
0dev.to Programming

My betting model looked great for 3,671 predictions. It never beat the bookmaker.
0dev.to TypeScript
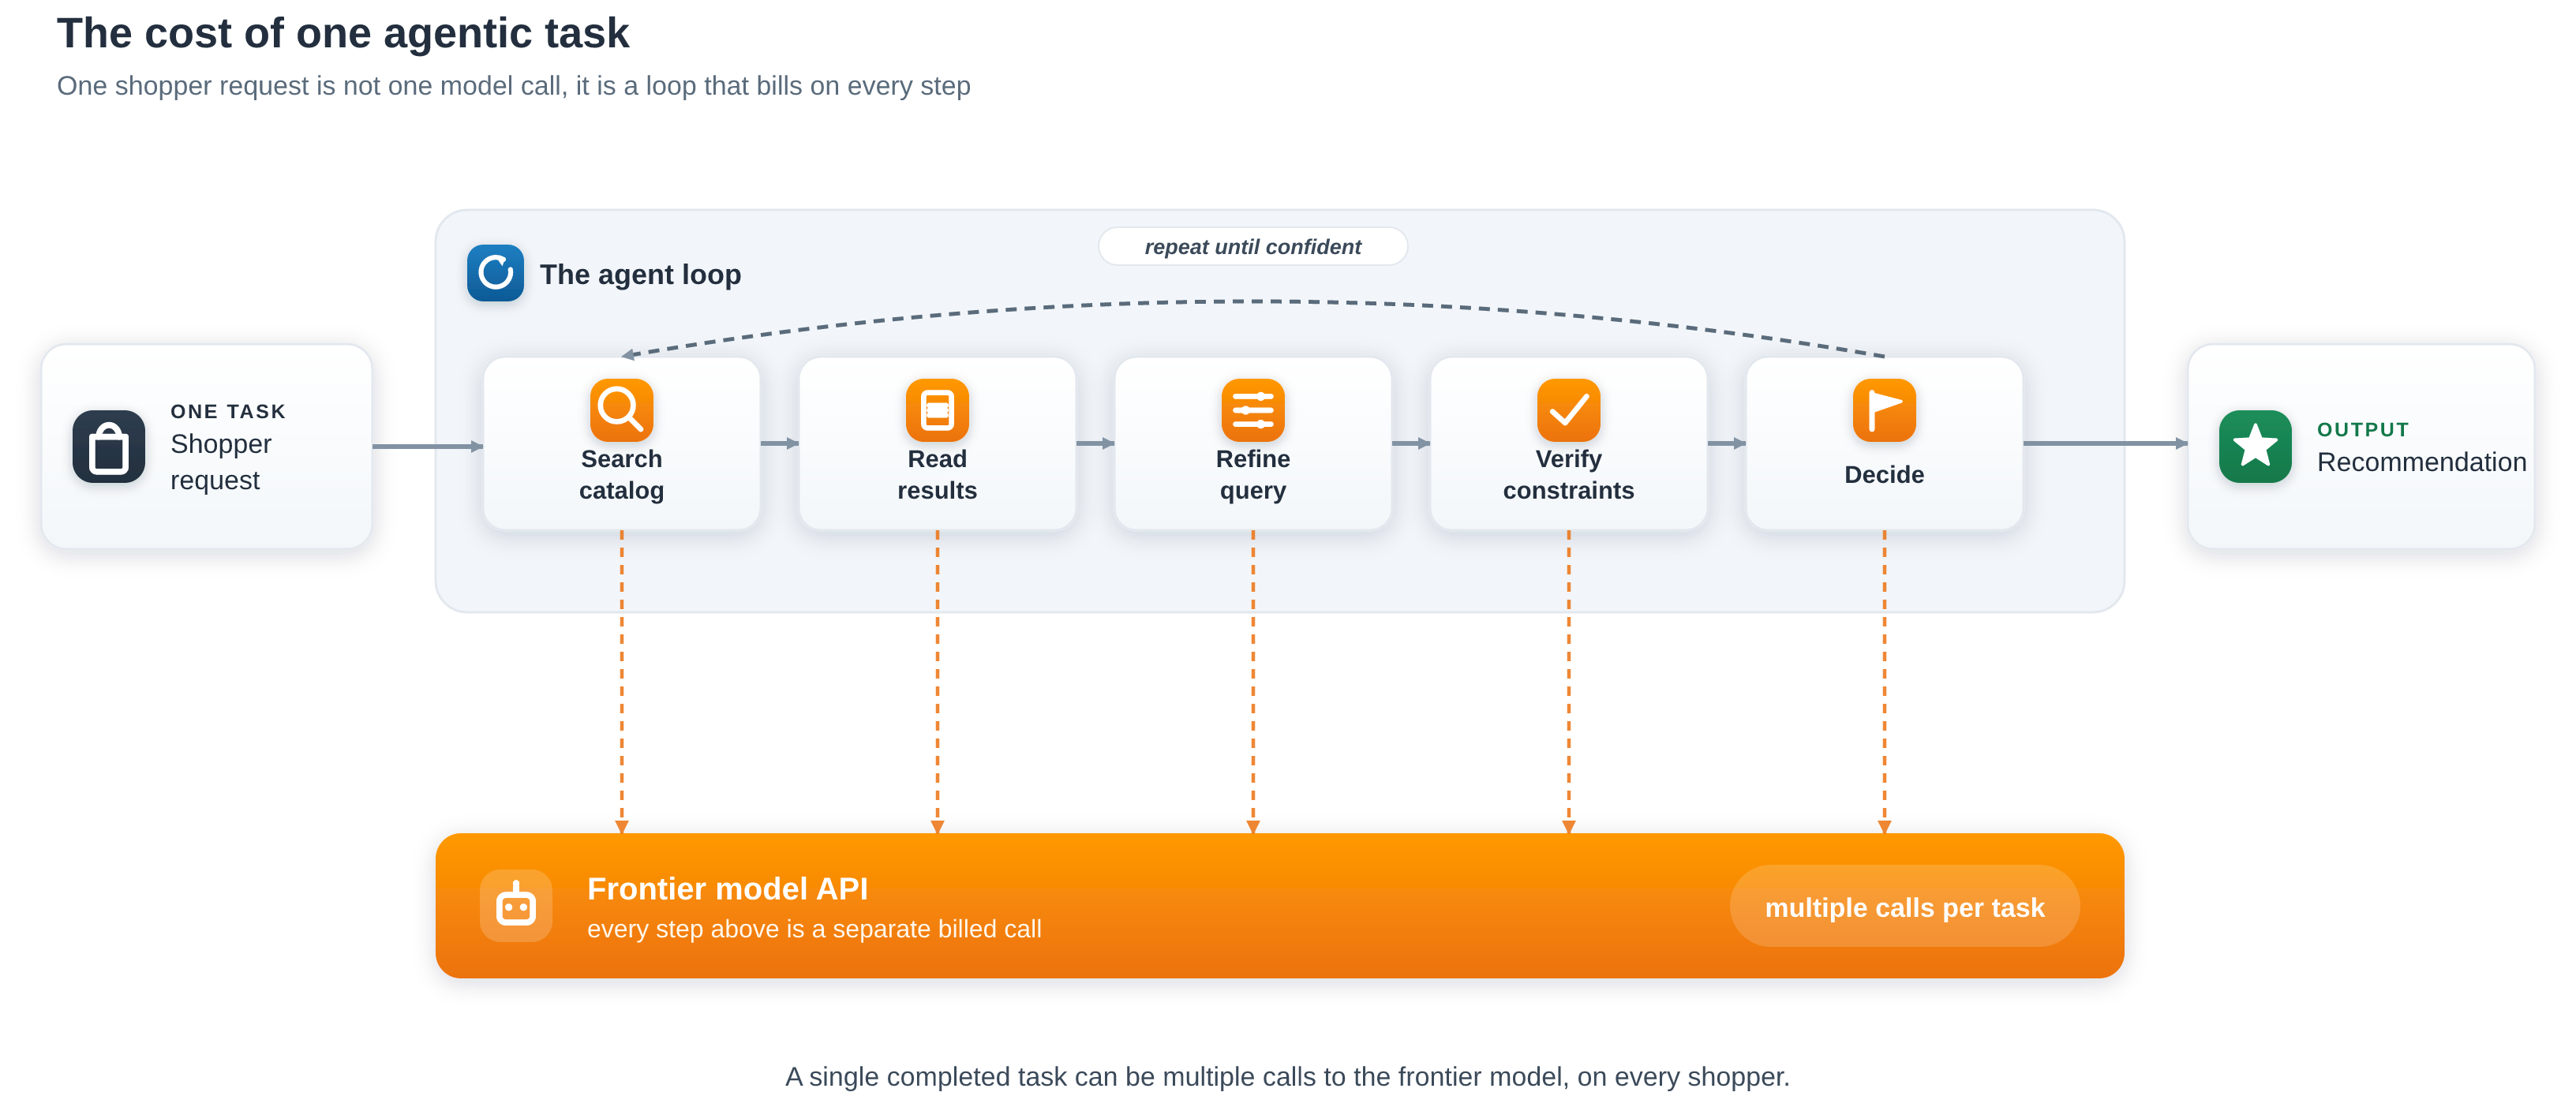
Build efficient agents with knowledge distillation on Amazon SageMaker AI
0AWS Machine Learning Blog