AI & ML
PRIME: Perception Feedback with Situational Memory Embeddings in VLA Models
arXiv cs.RO0 views
arXiv:2609.22040v2 Announce Type: replace-cross Abstract: Current Vision-Language-Action (VLA) models for autonomous driving operate primarily through feedforward inference across the perception--reasoning--planning hierarchy. While modern architectures maintain temporal recurrence within the perceptual module, early perception remains blind to downstream reasoning and navigation goals, processing visual inputs agnostically without prioritizing cues informed by prior decisions. To bridge this gap, this paper introduces PRIME, a learned feedback mechanism that conditions the VLA perceptual queries on a novel Situational Memory. By aggregating latent representations of past perception, reasoning, navigation goals, and predicted behaviors across an L-step window via cross-attention, PRIME enables intent-driven perceptual attention at minimal computational cost, adding only a maximum of 29.7M parameters (0.41% of the 7.3B-parameter base model). Evaluated on the Bench2Drive closed-loop benchmark, PRIME achieves a state-of-the-art Driving Score of 82.47 (+4.73 over ORION) and a Success Rate of 60.00% (+5.38 percentage points), the highest reported Driving Score among published VLAs trained on Think2Drive demonstrations.
Source:https://arxiv.org/abs/2609.22040PreviousRollback the World, Keep the Reflection: Rollback-Induced Reflection for Long-Horizon LLM AgentsNextActionUNet: Improving Robustness of VLA Models with Efficient Multi-scale Fine-tuning
Related posts
Introducing automatic version upgrades for AWS Glue jobs
0AWS Big Data Blog
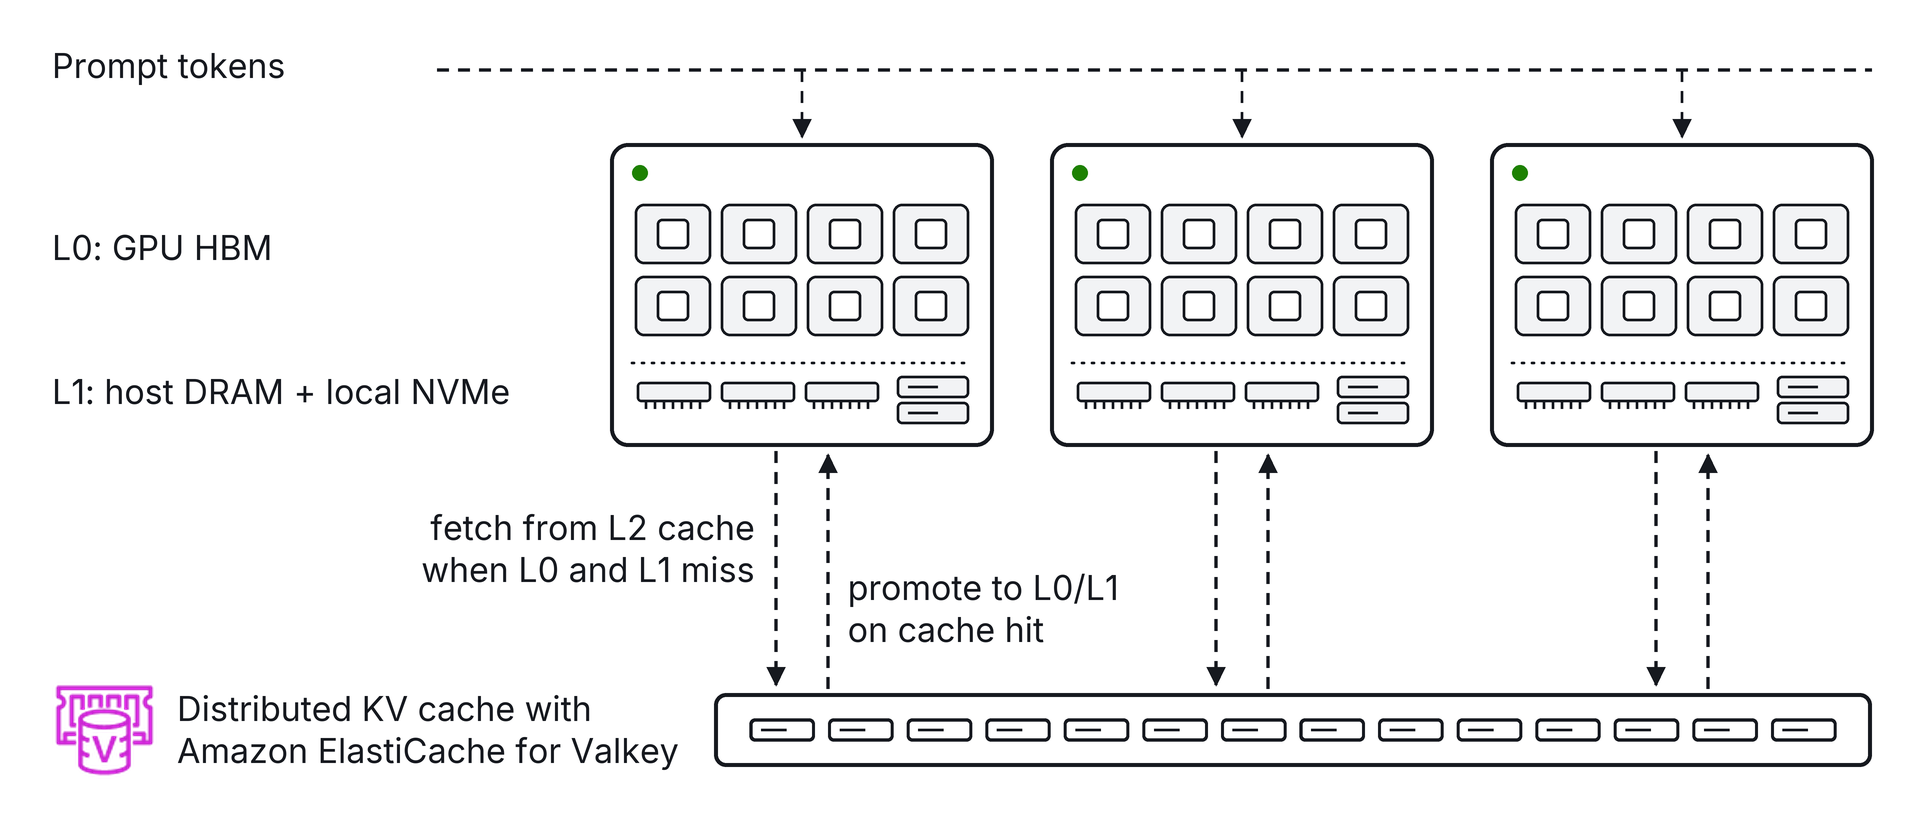
Announcing distributed KV caching for self-hosted LLMs with Amazon ElastiCache
0AWS Database Blog
Exa boosts embedding throughput by 50% to index billions of documents on AWS AI chips
0AWS Machine Learning Blog

BEVCast: Path-Adaptive BEV for Efficient End-to-End Autonomous Driving
0arXiv cs.RO

World-Model Gradient Refinement in CEM: An Empirical Study
0arXiv cs.RO

Rollback the World, Keep the Reflection: Rollback-Induced Reflection for Long-Horizon LLM Agents
0arXiv cs.RO