
Hold an iPhone near a sticker and something happens. A business card lands in your contacts, a focus session ends, or a door opens. The chip costs about twenty pence and holds roughly a hundred and thirty bytes.
Reading one takes two function calls. Earning the right to make those two calls takes considerably longer. And then CoreNFC asks you to earn it a second time.
The first gauntlet is Apple's. A paid developer account, an App ID registered in a web portal, a capability ticked on it, and a provisioning profile regenerated. Get any of it wrong and the build fails with a code-signing error that never says the word "NFC".
The second is CoreNFC's own, and it's the one nobody warns you about. It's a session-based API with delegate callbacks, four nested asynchronous steps, and a set of rules that punish you quietly.
Hold the session in the wrong variable and the system sheet vanishes with no error at all. Let a successful read settle your promise twice and your result is replaced by a failure. Ask for one polling option too many and the whole session refuses to start, without naming the option.
In this handbook, you'll get through both. You'll write an NDEF decoder by hand, which sounds like overkill until you read what the popular library's one actually does to an emoji. You'll write to a tag and discover your business card doesn't fit. You'll build a focus timer you can't stop without walking to another room. You'll delete the NFC dependency entirely and replace it with a native module in Swift. And you'll permanently lock a tag, which is the one thing here that can't be undone.
Two of the things I concluded during this build turned out to be wrong, and both are still in the repository under "superseded" banners. They're in here too, because how I got them wrong is more useful than the what replaced them.
This is an iOS handbook. Everything in the main sections was built, run, and verified on a real iPhone. Android gets its own handbook, and if you can't wait for it there's a preview at the end: the Kotlin counterpart to everything here, with the architectural differences that make the two platforms worth comparing.
Everything below comes from one project, TapCard, which is on GitHub with tagged checkpoints so you can check out the app at any stage and run it.
Table of Contents
Prerequisites
To follow along you'll need:
A physical iPhone, 7 or newer. Core NFC is iPhone-only. Apple's documentation lists iPhone 7 and later, and an Apple engineer on the developer forums puts it directly: "At this time, CoreNFC functionality is only available on iPhones with NFC capability." No iPad supports it.
A paid Apple Developer account. NFC isn't available on a free provisioning profile. This isn't a soft requirement, and there's no way around it.
NTAG213 stickers. Twenty of them cost a few pounds. Buy them before you write any code.
Node 20+ and Xcode. Working knowledge of TypeScript throughout, and of Swift for the last third.
Optional, for the Android preview only: Android Studio and the API 36 SDK.
The versions I used:
| Package or tool | Version |
|---|---|
| Expo SDK | 57.0.20 |
| React Native | 0.86.3 |
| React | 19.2.3 |
| TypeScript | 6.0.3 |
react-native-nfc-manager | 3.17.2 (removed by the end) |
| Xcode | 26.6 |
| JDK | 17 (Zulu), Android preview only |
One line in that table is load-bearing and I'll come back to it: the NFC library is listed because it gets deleted. The finished app has no third-party NFC dependency at all.
What NFC Tags Actually Are
An NFC tag is a chip with a tiny antenna and no battery. Your phone powers it over the air, and in return it hands back a few dozen bytes. That's the whole device.
Those bytes are almost always formatted as NDEF, or NFC Data Exchange Format, which is the thing that makes a tag written by one app readable by every other. An NDEF message is a list of records, and each record has a type and a payload.
The tags in this handbook are NTAG213, the ones you'll get if you buy stickers online. They hold 144 bytes of user memory. That's not the number you can actually use, and it turns out to matter enormously.
Two things a tag is not:
It's not a beacon. It has no power of its own and does nothing until a phone is within a couple cm.
It's not secure by default. Its identifier is world-readable and copyable with cheap hardware. There's a section on this later, because the obvious use of a tag, as a key, is the one most likely to be built wrong.
Where You Have Already Seen This
NFC is in your pocket already, and it's worth separating what you can build from what you can't, because they look identical to a user.
Here are five uses cases you can go and check, each one documented by the company that ships it:
| Where you have seen it | What happens | Source |
|---|---|---|
| Shortcuts, on your own phone | Scan a tag to fire a personal automation | Setting triggers in Shortcuts |
| A lost AirTag | Anyone taps it with an NFC phone and a page opens with the owner's details | Mark an item as lost in Find My |
| Nintendo amiibo | A figure is tapped to a controller. Some games read it, some write your character back onto it | amiibo FAQ |
| A UK visa application | The "UK Immigration: ID Check" app reads the chip inside your passport | Using the app |
| Tap to Pay on iPhone | A shop takes a contactless card payment with no terminal at all | Tap to Pay on iPhone |
The first three are the thing this handbook builds. A chip holds a few bytes, a reader reads them, and software acts. amiibo is the most complete example of the lot, because some games write to the figure as well, which is the second half of what you're about to build.
One detail on that first row is worth pausing on, because it comes back later. Apple's own NFC automation, the one built into every iPhone, says this about the tag you scan:
"Other than the unique identifier, the contents of the NFC tag are ignored."
Apple's feature ignores everything this handbook teaches you to write, and keys on the serial number alone. There's a section later on what that does and doesn't buy you.
Let's go over two caveats about that table. The passport row is NFC but it's not NDEF: a biometric chip speaks ISO 7816 over the same radio, through NFCISO7816Tag and a different entitlement again, with its own cryptography on top. Same antenna, different world, and out of scope here. And the last row is the half you can't build, which is the rest of this section.
Beyond those five use cases, the pattern repeats everywhere a physical thing needs to say one short sentence to a phone, like museum labels that open an exhibit page, conference badges, product-authentication seals on a bottle, transit posters, restaurant table markers, and the little stickers people put on a desk to start a routine.
What you can't build on iOS is the other half: your phone pretending to be a card. Apple Pay, your bank card in Google Wallet, or a hotel key in your Apple Wallet. Those run on the Secure Element, a separate tamper-resistant chip that stores card credentials and answers terminals on its own. On iOS there's no third-party API for it at all. Not restricted: absent. There's a section later on exactly how closed that is.
So when someone says "NFC", they may mean either. This handbook is about the half you can actually write code for, and it'll explain precisely why the other half is closed.
Why There Is No Simulator Path
Don't skip this section, because it changes how you work.
NFC doesn't exist on the iOS Simulator or the Android emulator. It's not partially supported, nor is it behind a flag. The hardware isn't there and the APIs report it as unavailable. Every single thing you build is tested by holding a physical chip against a physical phone.
The consequences go beyond inconvenience. You can't write a test that proves a tag was read. You can't demo it in CI. If your phone is in another room, you're blocked. When my chips went missing in the post, the project stopped for two weeks.
The app says so permanently, because the question kept coming up:
import * as Device from 'expo-device'; // NFC hardware does not exist on the iOS Simulator or the Android emulator, // and isSupported() is not reliable there. Bail out early and explicitly. if (!Device.isDevice) return false; So split your code in two.
One part talks to the NFC hardware. Start a session, read the tag, write to it, and close the session. The only way to test that part is to hold a chip against a phone.
Everything else is just data handling: turning the bytes off a tag into a URL, turning a contact into the bytes you write back, checking whether a message fits, turning a native error code into a sentence a user can read, or deciding whether a tap should start a focus session or end one.
None of that needs NFC. Most of it doesn't even need React Native. It's plain functions: values go in, values come out.
Write it that way and you can test it on your laptop, with no phone in the room. In this project, that came to about 2,240 lines of TypeScript and 293 tests that finish in about a second. The code that actually calls CoreNFC stays as small as I could make it.
This project stalled on hardware three times, including those two weeks waiting on the post. Each time there was still plenty left to build, because most of it never needed a tag. That's the best decision in the codebase, and I didn't make it deliberately. The constraint made it for me.
Checkpoint:
git checkout step-0-scaffold. The app boots on both platforms and does nothing else.
How the iOS Contract Works
Three Apple terms do all the work here, and they're worth pinning down before the steps, because the error messages assume you already know them.
An App ID is the identity your app is registered under on Apple's servers, matching the bundleIdentifier in your config. An entitlement is a line in your app saying "I intend to use this capability", and NFC is one. A provisioning profile is the signed document tying the two together with your developer account, and Xcode embeds it in every build. All three have to agree, or nothing runs on a device.
With that, here's the actual sequence, and every step is important:
A paid Apple Developer account.
An explicit App ID registered at developer.apple.com, not a wildcard.
NFC Tag Reading ticked on that App ID.
A provisioning profile regenerated to include the capability.
Then, in app.json:
{ "expo": { "ios": { "bundleIdentifier": "com.yourname.tapcard", "infoPlist": { "NFCReaderUsageDescription": "TapCard uses NFC to read and write your card to a tag." }, "entitlements": { "com.apple.developer.nfc.readersession.formats": ["NDEF", "TAG"] } } } } Miss step 2 or 3 and the build fails with this:
Provisioning Profile "iOS Team Provisioning Profile: *" does not support the NFC Tag Reading capability. That error points at the wrong machine. Apple forbids special capabilities on a wildcard App ID, and Xcode silently falls back to one when there's no explicit match.
The message blames your local provisioning profile, but the missing half is on Apple's servers, in a web form you haven't filled in. Nothing in it suggests opening a browser.
A second-order trap while you're there: App IDs are globally unique across all Apple accounts, not per-team**.** My first choice was taken by a stranger, and my second was too. I renamed the app's identifier twice.
Those renames were painless, and that's worth a word on how this project is set up. Expo's Continuous Native Generation means the ios/ and android/ folders aren't kept in the repo at all. They're regenerated from app.json by expo prebuild whenever you need them, the way node_modules is regenerated from package.json. So renaming the app was two lines of JSON and one prebuild --clean, which rebuilt the iOS project, the Android package and the entire Kotlin source tree. No Xcode surgery.
For scale, the equivalent on Android is one line in a manifest, with no account, no portal, and no cost:
<uses-permission android:name="android.permission.NFC" /> That contrast isn't a complaint. It's worth internalising early, because it tells you where your time will go on this platform: not in the code, which is short, but in the paperwork around it.
| Android | iOS | |
|---|---|---|
| To read one tag | One manifest line | App ID + capability + paid account + profile |
| Cost | Free | $99/yr, or local equivalent |
| Failure mode | Permission missing | A code-signing error that never says "NFC" |
How to Read Your First Tag
The reading code is short. This is all of it:
import NfcManager, { NfcTech, type TagEvent } from 'react-native-nfc-manager'; export async function readTagOnce(): Promise<TagEvent | null> { await NfcManager.requestTechnology(NfcTech.Ndef, { alertMessage: 'Hold your iPhone near the NFC tag.', }); try { return await NfcManager.getTag(); } finally { // throwOnError: false because we are already unwinding. A failure to // close the session must not mask the original error. await NfcManager.cancelTechnologyRequest({ throwOnError: false }); } } There are two calls, and they're identical on both platforms. And what the user sees couldn't be more different.
On iOS, requestTechnology hands control to CoreNFC, which draws a system modal sheet. You can't restyle it. Your app isn't on screen.
On Android, nothing is drawn at all. Dispatch is silent. If your app doesn't tell the user to tap a tag, nobody does.
So the scanning UI is conditional, and this pattern recurs through the whole project:
{ scanning && ( <View style={styles.scanCard}> <ActivityIndicator /> <Text> {Platform.OS === 'android' ? 'Hold a tag against the back of the phone.' : 'Waiting for the system NFC sheet…'} </Text> {/* Android draws no system UI, so the app must offer its own way out. */} {Platform.OS === 'android' && <Button title="Cancel" onPress={handleCancel} />} </View> ); } That Cancel button exists only on Android, because on iOS the system sheet already has one.
Three Things That Will Catch You
1. The antenna is in different places.
On iPhone: the top edge, near the camera. On Android: the middle of the back. "Hold the tag near the phone" isn't actionable, and someone using the wrong end concludes your app is broken. I ended up drawing a small phone outline with the dot in the right place per platform.
2. The sheet doesn't show the string you think it does.
I assumed it displayed NFCReaderUsageDescription from app.json. It doesn't. It shows the alertMessage passed to each requestTechnology() call. The usage description is a privacy-manifest string: it's mandatory, no session starts without it, and it's never shown to a user.
Both strings were configured correctly and spelled properly, and my assumption about which one appeared was still wrong. I found out by holding a phone. It also means the copy can differ per scan. "Hold your iPhone near the tag to write" beats reusing the read copy.
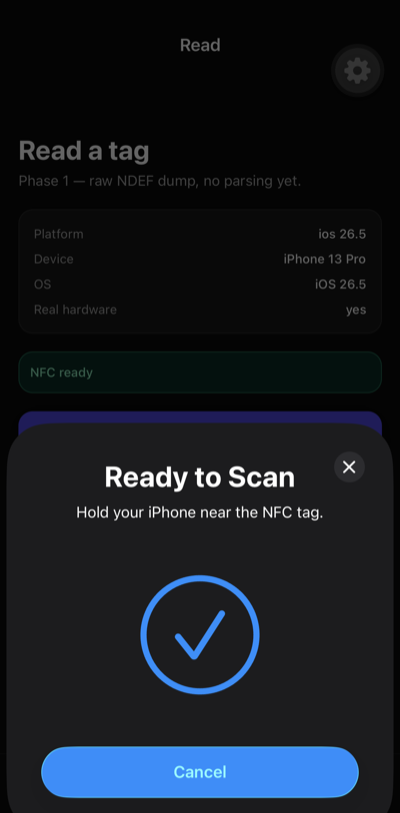
That second line is the alertMessage from the requestTechnology call above, word for word. The usage description from app.json is nowhere on screen.
3. A blank tag reads as an error on iOS.
A factory-fresh NTAG213 is NDEF-formatted but empty, and readNDEF reports that as a failure rather than an empty message. The distinction has to come from the tag's NDEF status, not the read error. Since every tag you buy starts this way, it's the first thing you'll hit.
What Comes Back
Here's the real output from an NTAG213 on an iPhone 13 Pro:
{ "id": "04C4FC91DF2A81", "tech": "mifare" } Two fields. That's everything iOS gives you from a read. No size, no technology list, and no NDEF type. Android returns all of them from the same chip.
I drew the wrong conclusion from this: wrote it into three documents, and planned a whole phase of work around it. That comes later, because the mistake is more useful than the fact. Skip ahead if you'd rather have the correction now.
That id is the tag's UID, a unique serial number burned into the chip at the factory and readable by anything that asks. The 04 prefix is NXP's manufacturer code, and a 7-byte UID is the NTAG21x signature, so the tag is what it claimed to be.
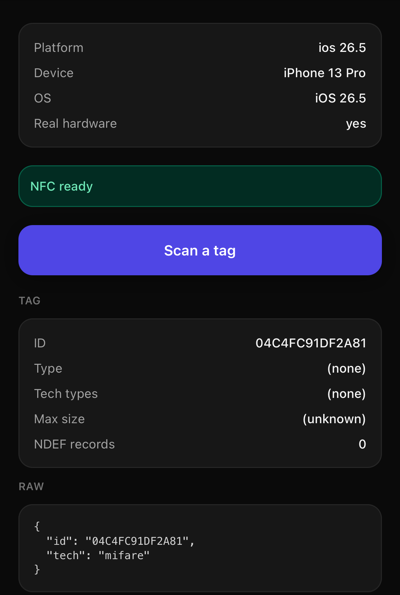
The Max size row is the one to look at. (unknown) is what I built the wrong conclusion on, and it is not what the platform can actually tell you.
Checkpoint:
git checkout step-1-first-read. Entitlements configured, a raw NDEF dump on screen.
What an NDEF Record Actually Is
A tag doesn't store a URL. It stores bytes, and bytes are what your app gets handed. This whole section is about turning those bytes into https://example.com and back, and it's a much smaller job than its reputation suggests.
The unit you work with is a record, and a record is three things:
a payload: the raw bytes of the content
a type: what that payload is, such as a URI or some text
a TNF, or Type Name Format: three bits saying how to read the type field itself
That third one is the one people trip on. Think of the type as a label and the TNF as the rule for reading the label. A type byte of U means "URI", but only because the TNF said "this is a well-known NFC Forum type". The same byte under a different TNF would be the start of a MIME string instead.
Two record layouts carry almost all real traffic, and both are tiny.
A URI Record
04 65 78 61 6d 70 6c 65 2e 63 6f 6d │ └──────── "example.com" ────────┘ └─ prefix index → "https://" → https://example.com The annotations underneath say which byte does what. Everything after the first byte is ordinary text: example.com. The first byte, 04, is an index into a 36-entry table in the NFC Forum spec, and entry 4 is https://.
So the scheme costs one byte instead of eight. On a tag with 137 usable bytes that isn't a micro-optimisation, it's 5% of your budget.
A Text Record
Text needs two things a URI doesn't: which language it's in, and how it's encoded. Both get squeezed into the first byte.
02 65 6e 48 69 │ └─┬─┘ └─┬─┘ │ "en" "Hi" └─ status byte Read that first byte as a number. Here it's 2, and that's how long the language code is. So the next two bytes are the language: 65 6e, "en". Everything after that is the text: 48 69, "Hi".
The encoding hides in the same byte. If its value is 128 or more, the text is UTF-16 instead of UTF-8. That's all a "status byte" means.
That's the whole format. If you're writing the decoder yourself, mask off the low six bits for the length and test the top bit for the encoding.
Why I Wrote My Own Decoder
You reach past a library for one of two reasons. Either it doesn't give you everything you need, or you work somewhere that builds this kind of thing in-house first and takes dependencies second.
The second is more common than the open-source default makes it sound, and for NDEF it has a short answer: yes, you can write this yourself. It's a few hundred lines of pure functions with no platform calls in them, and the format you just read is the whole specification you need.
The first reason is what actually happened here. The library bundles decoders, I read them before using them, and twenty minutes changed the architecture of the app.
It throws away the language code. In ndef-lib/ndef-text.js:
var languageCodeLength = data[0] & 0x3f; // 6 LSBs // languageCode = data.slice(1, 1 + languageCodeLength), // utf16 = (data[0] & 0x80) !== 0; // assuming UTF-16BE // TODO need to deal with UTF in the future It measures the language code's length, uses it to skip past the code, and the line that would keep it is commented out. decodePayload returns a bare string, so a caller can't recover the language at all. "Which language is this in?" is precisely the question a record with a language field exists to answer.
That TODO is load-bearing. UTF-16 text records are decoded as UTF-8 regardless, producing interleaved NUL characters.
And the shared byte-to-string helper truncates. In ndef-lib/util.js:
str += String.fromCharCode(ch); String.fromCharCode only keeps the low 16 bits, and an emoji doesn't fit in 16 bits. So I fed it one:
bytes : 68 69 20 f0 9f 98 80 expected : hi 😀 library : "hi " codepoints: 68 69 20 f600 ← U+F600, Private Use Area U+1F600 became U+F600, an invisible character. Three-byte sequences, such as Arabic and CJK, are fine, so the bug hides until someone uses an emoji.
Its URI decoder, meanwhile, is eight lines and completely correct. That asymmetry is the interesting part. This isn't a bad library. It's a library with two stale corners. The only way to know which is which was to read it.
So I wrote the decoder and kept the library for the part that actually talks to the hardware. About 530 lines, all of it plain TypeScript with no React Native imports, which means it runs in Node and tests in milliseconds.
Its job is to turn a record into one of a few known shapes, and that's what this type describes:
export type NdefView = | { kind: 'empty' } | { kind: 'uri'; uri: string } | { kind: 'text'; text: string; lang: string; encoding: TextEncodingName } | { kind: 'mime'; mime: string; text?: string; bytes: number[] } | { kind: 'aar'; packageName: string } | { kind: 'unknown'; tnf: number; type: string; payload: number[] }; Why a union of shapes, rather than one object with lots of optional fields? Because with optional fields, every screen has to guess which ones are filled in. Here you check kind once and TypeScript knows the rest. On a record where kind is 'text', .uri doesn't exist. So a screen that tries to read it fails to compile instead of rendering undefined to somebody holding a phone.
The unknown case still carries the raw tnf, type, and payload, so a record nothing recognises can at least be shown as a hex dump. A reader that silently drops what it doesn't understand is worse than one that says "I don't know what this is, here are the bytes".
One platform difference is buried inside the decoder itself. A record's type field arrives as raw bytes on Android, and sometimes as an already-decoded string on iOS. So the same URI record turns up as [85] on one platform and 'U' on the other, 85 being the byte for the letter U.
That matters because [85] === 'U' is just false. There's no error and no warning: your comparison quietly fails to match, and a perfectly good URI record falls through to "unknown record". Convert the type to a string before you compare it, on both platforms.
Test Against the Thing You Replaced
This is the technique I'd most like people to steal. The tests come in three groups.
Correctness: the decoder against hand-built payloads.
Agreement: where the library is right, prove we match it exactly. Twelve real URIs encoded by the library and decoded by us, plus all 36 prefix indices. That's the cheap way to be confident about a lookup table you typed out by hand.
Divergence is the strange one. Where the library is wrong, write a test that locks in exactly how it's wrong:
✓ the library discards the language code; we keep it ✓ the library truncates 4-byte UTF-8; we do not ✓ both handle 3-byte sequences, so only characters above U+FFFF break ✓ the library ignores the UTF-16 flag; we honour it That looks backwards. You're writing tests that pass because a dependency is broken, and normally that's a smell.
Two things earn them their place. Each one is a written record of why your own code exists, sitting next to the code instead of in a commit message nobody reads. And because they assert the library's current behaviour, they start failing the day somebody upstream fixes it.
That failure is the whole point. It isn't a broken test, it's a notification: the reason you wrote your own decoder may have just gone away, and you can go and check. A comment saying "the library is buggy" rots quietly while the library changes around it. A test saying so can't.
One detail decides whether these tests are useful or useless. The emoji test asserts the exact wrong answer, the code point 0xf600, rather than just "the library disagrees with us".
If it only checked for disagreement, a future version with a different bug would still pass, and you would never notice the behaviour had changed. Pinning the specific wrong value means any change at all shows up, whether upstream fixed the bug or replaced it with a new one.
Checkpoint:
git checkout step-2-decode. Own decoder, a Tag Info screen showing every field and the raw bytes.
How to Write a Tag
Now the other direction. Two options, and they're opposite trades rather than variations.
A URL record is tiny, and every phone opens it with no app installed. It's what most commercial NFC business cards do. It also needs something at the other end: a domain that stays renewed, a server that stays up, or a network connection at the moment someone taps.
A vCard is the whole card. text/vcard as a MIME record, no server, works on a plane. It's also much bigger.
I built both and let the user choose, because the numbers make the argument better than copy could.
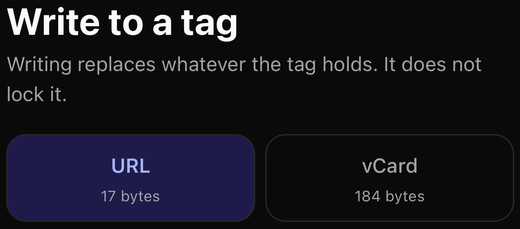
Seventeen bytes against 184, for the same person's contact details. That gap is the entire trade, and it's why the choice sits in front of the user instead of being made for them.
How to Encode a vCard
A vCard is just text. This is what the app actually writes onto the tag:
BEGIN:VCARD VERSION:3.0 N:Doe;Jane;;; FN:Jane Doe ORG:Example Ltd TITLE:Full-stack engineer TEL;TYPE=CELL:+15550100 EMAIL;TYPE=INTERNET:jane@example.com URL:https://example.com END:VCARD One field per line: a name, a colon, a value, and a carriage return plus newline at the end of every one. Build that string and you have a working card.
The format is from the 1990s and it shows, though, and three of its rules are easy to get wrong. Your encoder has to handle all three.
1. Fold long lines by octets, not characters.
Any line longer than 75 bytes has to be broken and continued on the next one, starting with a space. The obvious way to do that is line.slice(0, 75), which counts characters rather than bytes, so it can cut a two-byte character in half and leave invalid UTF-8 on the tag. Walk the string by code point instead, tracking the byte cost as you go.
2. Emit N, and be up front that you're guessing.
Look at that N: line. vCard 3.0 wants the name split into Family;Given;Additional;Prefix;Suffix, so emitting FN on its own isn't enough. Splitting a display name into those parts is guesswork, and the guess is wrong for Chinese and Hungarian names, for Spanish names with two surnames, and for anyone who goes by a single name. I take the last token, document that it's a guess, and let FN, which is what importers actually display, carry the name exactly as typed.
3. Escape every semicolon inside a value.
The semicolons on that N: line are structural. If someone's job title were "Engineer; Lagos", writing it straight through would turn one field into two and an importer would read the rest as part of the name instead. It has to reach the tag as Engineer\; Lagos.
Get those three right and the whole encoder is about 170 lines of pure string handling, testable without a tag anywhere near it.
The Escaping Bug That Passed Its Tests
That third rule is where my worst bug lived. My escaper had this line:
.replace(/;/g, '\;') // ← this escapes nothing vCard wants a literal backslash in front of any semicolon inside a value. '\;' looks like it produces one. It doesn't. JavaScript has no \; escape sequence, so it quietly drops the backslash and hands back a plain ';'. That line was replacing every semicolon with itself.
The fix is '\\;', where the first backslash escapes the second.
Then it got worse. I wrote a test for the escaper and asserted the unescaped output, because I still believed the line worked. The test agreed with the bug, which means it would have failed against correct code.
Then a third test tried to prove a field was absent with not.toContain('N:'). That can never pass. Every vCard starts with BEGIN:VCARD, and BEGIN: ends in N:.
Three mistakes in ten minutes, all the same misunderstanding.
Test-first wouldn't have saved me. The test and the code shared the assumption. String escaping is a domain where they usually do.
Ask the Tag Before You Write to It
A write replaces what's on the chip. The order matters:
1. Query the tag: is it writable, how big is it really? 2. Refuse early: read-only, or genuinely too small 3. Write 4. Read it back: compare with what you sent Step 2 is the safety property. A refusal before the write leaves the tag untouched, while a failure during one can leave it half-written.
Step 4 exists because a write that reports success and didn't happen is the worst outcome available. Read back inside the same session and compare record content, not raw bytes. A tag may legally return a message whose framing differs from what you sent while carrying identical data.
All four in one session, not four. On iOS each requestTechnology puts a system sheet in front of the user, so splitting them means four sheets and four taps for one logical action. Android wouldn't notice the difference, which is exactly the sort of thing that makes an iOS-shaped design look arbitrary until you see it on the other platform.
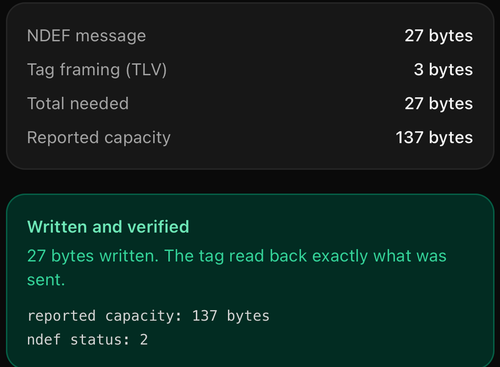
You have all four steps in one screen: the tag was asked, the numbers came back measured rather than assumed, the write went out, and the read-back confirmed it byte for byte.
Checkpoint:
git checkout step-3-write. Profile editor, vCard encoding, writing with a capacity check.
Will It Fit? 137, Not 144
Here's where the project taught me something.
An NTAG213 has 144 bytes of user memory. That number is in every spec sheet: 36 pages of 4 bytes, pages 4 through 39. I built the capacity check around it.
A realistic vCard (name, title, company, phone, email, one link) comes to 184 bytes of text and 202 bytes once it's wrapped as an NDEF message, which is the figure on the toggle a few sections back.
So an ordinary business card doesn't fit on an ordinary tag. That's a genuine product constraint, not a bug, and the app has to say so rather than fail mysteriously.
Except my number was wrong. When I finally asked a real tag how big it was, it said 137.
144 is the chip's user memory. The number that matters to a writer is the maximum NDEF message, which is smaller by the tag's own bookkeeping. I had been seven bytes too generous, in the direction that tells someone their card fits when it doesn't.
The error hid a second one. A tag doesn't store your message bare: it wraps it in a few bytes of its own bookkeeping, called TLV framing, for type, length and value. I'd been adding those bytes to the message and comparing against user memory. Double-counting. Every capacity figure in play (Android's getMaxSize(), iOS's status query, a sensible assumption) is already a message size with framing excluded.
The Bigger Mistake
Worse than the number was what I'd concluded about the platform.
Because iOS's getTag() returns only { id, tech }, I concluded iOS can't report tag capacity. I wrote that in the code, in the platform comparison, and in the app's own UI, and I planned a native module around closing the gap. Here it is, shipped:
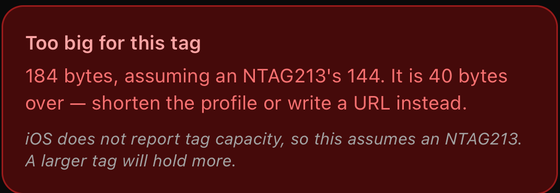
That italic line is the wrong conclusion, stated to the user as fact. Every number in the card above it rests on the guess it forced.
It's false. ndefHandler.getNdefStatus(), which is CoreNFC's queryNDEFStatus, returns both a read/write status and a real capacity, inside the session I was already opening. The capability was one call away from code that had been running for weeks.
Look at the shape of the mistake:
What I saw: one function,
getTag(), hands back two fields and no size. True.What I decided: iOS can't tell you how many bytes fit on a tag. That doesn't follow.
One function not answering a question doesn't mean the platform can't answer it. I tried one door, found it locked, and concluded there was no way into the building.
My rule for this project was that nothing gets written down as fact until I've seen it on a device. I followed it for the thing I measured. I forgot it for the thing I concluded from the measurement.
A conclusion you haven't checked is as dangerous as a number you haven't checked, and harder to catch, because it borrows the credibility of the real measurement sitting underneath it.
So the app now asks the tag, and only assumes when no tag has answered yet. When it assumes, it says so, every time:
Too big for this tag 202 bytes, assuming an NTAG213's 137. It is 65 bytes over. Shorten the profile or write a link instead. No tag has reported its size yet, so this assumes an NTAG213. Tags state their real capacity when you write to them. The word "assuming" appears whenever the number is assumed. It's repetitive by design: the moment the app stops saying it, a reader starts believing it measured something.
Here's the same card once a tag has answered:
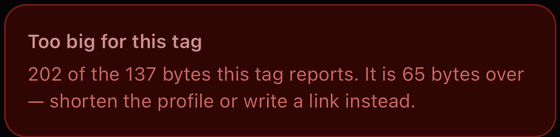
"This tag reports" instead of "assuming an NTAG213's". Same card, same layout, and the one word that changes is the one that says whether the number came from a chip or from me.
A Bug That Made This Harder to Find
My pre-flight check threw the library's own TagSizeTooSmall when a message wouldn't fit. So when a write failed, the error said TagSizeTooSmall, exactly what CoreNFC would have produced if it had rejected the write.
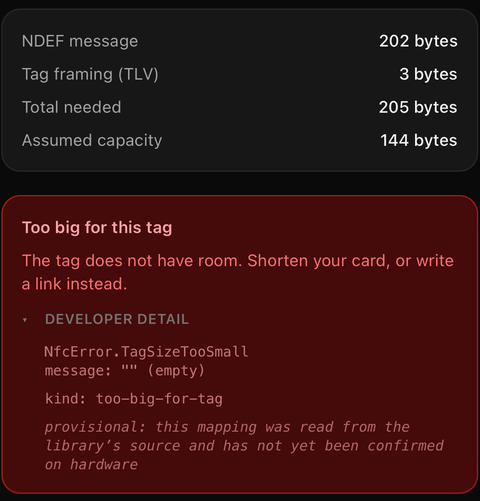
There are two things in that developer panel. NfcError.TagSizeTooSmall is the library's class, raised by my own code before the tag was ever consulted. And message: "" (empty) is the defect behind it: the class carried the entire meaning, and the string a screen would print carried none of it.
Our refusal and the tag's refusal were the same string. The one question I was trying to answer (did the platform report a capacity?) was the one the error had erased.
Never throw a dependency's error type from your own logic. It collapses "we refused" and "they refused" into one signal, and you'll want to tell them apart precisely when something is going wrong.
With a dedicated error type carrying the tag's own numbers, the answer was immediate:
WritePreflightError: too-big tag reported status 2, 137 bytes needed 202 bytes There it was. The platform had been reporting capacity all along.
Same screen, same chip, before and after:
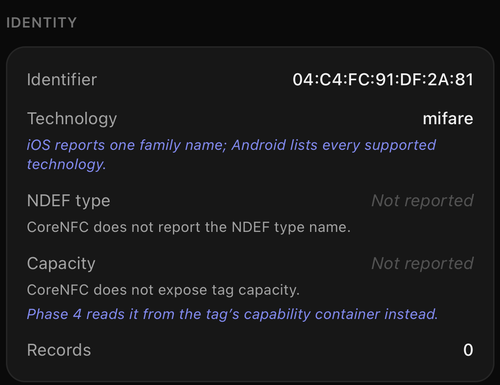
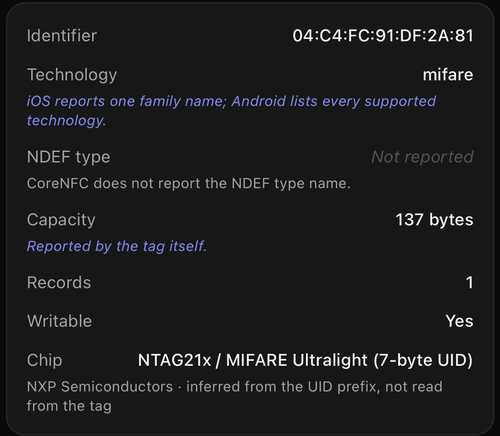
Every word under "Capacity" in the first shot is mine, and the confident one is wrong. The blue line beneath it is worse: a whole phase of native work, scheduled to close a gap that wasn't there.
The second reads a number, annotated reported by the tag itself, and nothing was added to the platform in between. Note what didn't change, though. "NDEF type" still says "Not reported", because that one genuinely isn't available. One question the platform can't answer, sitting directly above one it always could, which is exactly why I believed the wrong thing for so long.
A Focus Session You Can't End Without the Tag
A business card is a fine demo, but it only exercises half of what tags are good for. The other half is using a chip as a physical condition: something that must be true in the real world before software will do a thing.
So the app has a second feature: a focus timer you can't stop without walking to the tag.
You leave the chip somewhere inconvenient. Downstairs, in a drawer, at the back of a cupboard. Tap it to start a session. To end the session, you have to go back to it.
This idea isn't mine. Foqos (open source, on the App Store), TapBlok, nfcGuard, and Focusaur all converge on it, and they converge because the insight isn't about NFC at all:
The friction is geography, not the gesture. Tapping costs a second. What costs you is that the tag is downstairs. The tag's location is the product. NFC is merely what makes a location enforceable.
Three rules follow, and each is a line of code.
1. One tag, two meanings.
The same tap starts a session when idle and ends...


