General
Deliberative alignment: reasoning enables safer language models
OpenAI Blog0 views
Deliberative alignment: reasoning enables safer language models Introducing our new alignment strategy for o1 models, which are directly taught safety specifications and how to reason over them.
Source:https://openai.com/index/deliberative-alignmentPreviousWhy OpenAI’s structure must evolve to advance our missionNextOpenAI o1 and new tools for developers
Related posts

The beginning of a beautiful friendship? Interaction could be key to human acceptance of robots
0Phys.org Tech

Rosemary and Rubik's Cubes: How a scent helps us remember what we learn in mixed reality
0Phys.org Tech
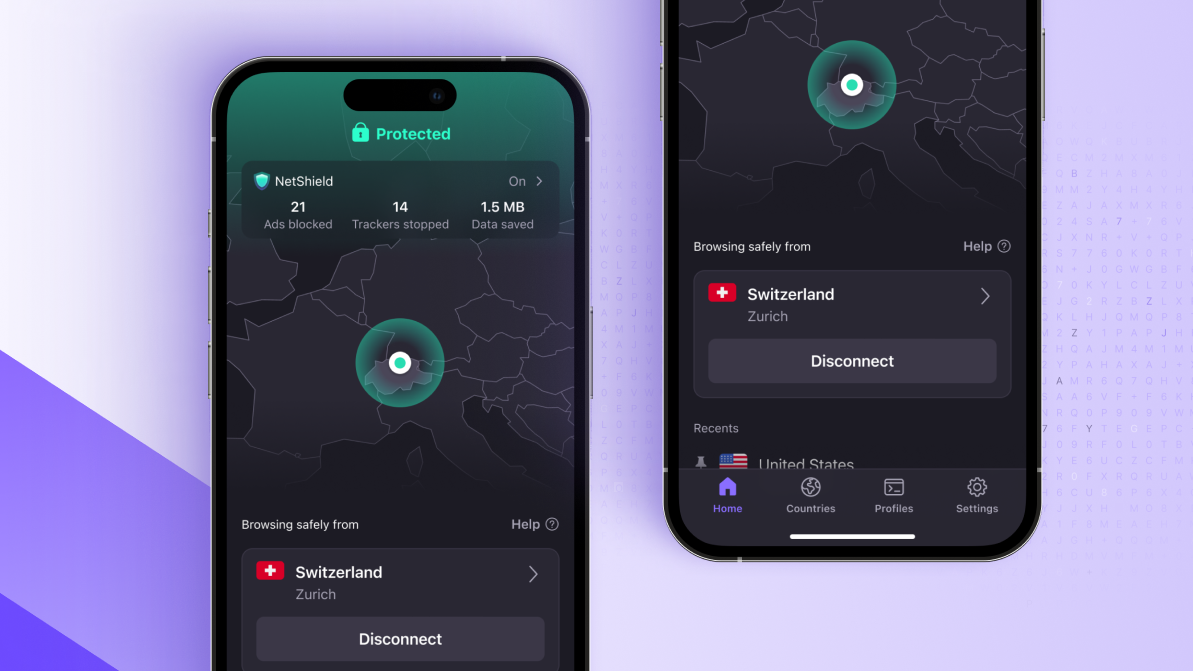
Your Proton VPN's iPhone app has just changed its look — here's all you need to know
0TechRadar
GTA 6 dev shares how Miami Vice, Heat, and Goodfellas are ‘touchstones’ for the latest game and how it channeled a sense of nostalgia of GTA Vice City — ‘I think the feeling of playing a movie that yo
0TechRadar
Tor hit by major DDoS attack, forced to release emergency update to users
0TechRadar

Injury-induced signalling coordinates immunity and cannibalism in locusts
0Nature News