AI & ML
XBot-Omni: An Omni-Modal Model for Embodied Understanding and Interaction
arXiv cs.RO0 views
arXiv:2611.17160v2 Announce Type: replace Abstract: Embodied interaction requires an agent to integrate multimodal perception with verbal and nonverbal behaviors to effectively communicate its intentions, including speech, body motion, and facial expressions. We present XBot-Omni, a Thinker--Talker--Actor architecture that extends the Omni paradigm to robotic modalities, including body motion and facial expressions, with ``X'' representing the extensibility to robotic-specific modalities. The Thinker processes text, images, audio, and video to formulate contextually appropriate responses, which are then realized by the Talker and Actor through speech and coordinated bodily expressions, respectively. In this report, we innovatively introduce the concept of ``Actor'' as a dedicated component for embodied agents: a coordinated, streaming module that leverages the native representations of the Thinker and Talker within an end-to-end pipeline, introducing only modest latency overhead. This unified architecture enables multimodal generation conditioned on omni-modal inputs directly to prevent information loss in staged designs. We comprehensively evaluate XBot-Omni across seven benchmarks, demonstrating strong multimodal understanding capabilities on both general-domain and robot-centric videos, as well as high-quality, natural, and well-coordinated motion generation. Furthermore, our results validate its capability to generate embodied multimodal responses directly from omni inputs, meeting the diverse requirements of embodied interaction. XBot-Omni enables robots not only to perceive the omni world but also to express themselves through speech and bodily behaviors, extending Omni models from conversational interaction to embodied communication in physical environments.
Source:https://arxiv.org/abs/2611.17160PreviousWhy Self-Review Fails in AI Coding Agents: Single-Agent Self-Review vs. an Adversarial Critic (0% vs. 100% Mutant Kill Rate)Next3D-MoE: Towards Spatial Intelligence with Mixture-of-Experts for 3D Reasoning and Action Generation
Related posts
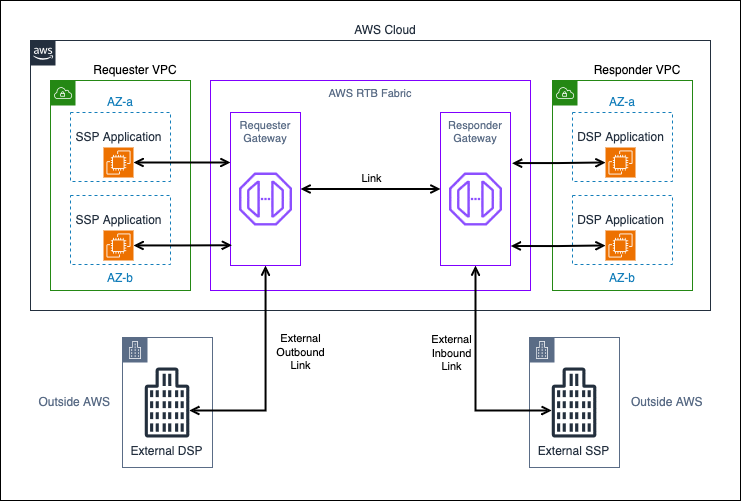
Building highly available real-time bidding workloads with AWS RTB Fabric
0AWS for Industries

Thống kê đối đầu Rayo Vallecano vs Valencia: Xu thế bế tắc và quy luật chia điểm áp đảo
0dev.to Data

Phân tích dữ liệu đối đầu Alaves vs Deportivo La Coruna: Ưu thế phòng ngự tuyệt đối của đại diện xứ Basque
0dev.to Data

Thống kê đối đầu Arsenal vs Newcastle: Thế trận phân định tuyệt đối và dấu ấn phòng ngự
0dev.to Data

Tương quan thông số vòng 8 V.League 1: Thể Công - Viettel chạm trán Sông Lam Nghệ An
0dev.to Data

Into the Breach: Show the Threat, Not the Answer
0dev.to Design